By Sagi Shaier · 11 October 2026 · 6 min read
Einsum explained with examples (torch.einsum)
How to read an einsum string like 'bik,bkj->bij', which letters get summed and which stay, and how to write the dot product, matrix multiplication, transpose, batched matmul, elementwise product, and outer product with torch.einsum.
Einsum (short for Einstein summation) is a notation for multiply-and-sum operations on tensors, where a short string of letters names each tensor's axes and says which axes survive into the result. In PyTorch it is torch.einsum, and NumPy has the same function as np.einsum. Research code and papers use it often, because the string states exactly which axes get summed, so a reader can check the shapes without running anything.
What problem does einsum solve?
Many tensor operations are the same pattern underneath: multiply entries that line up, then add some of the products together. The dot product of two vectors multiplies matching entries and adds all the products. Matrix multiplication does that for every row of the first matrix against every column of the second. PyTorch gives each one its own function or operator. Matrix products use @ and elementwise products use *. Transposes use .T or .transpose, and batches of matrix products use torch.bmm.
When an operation has three or four axes, it becomes hard to tell from those calls which axis is multiplied against which. Einsum writes every one of these operations in a single format, with the axes named.
How to read an einsum string
An einsum string has two parts separated by an arrow ->. Left of the arrow is one group of letters per input tensor, separated by commas, with one letter per axis. Right of the arrow are the letters of the output.
Three rules turn the string into an operation:
- Entries whose letters match get multiplied together.
- A letter that appears in the inputs but not in the output gets summed over.
- A letter that appears in the output stays as an axis of the result, in the order written.
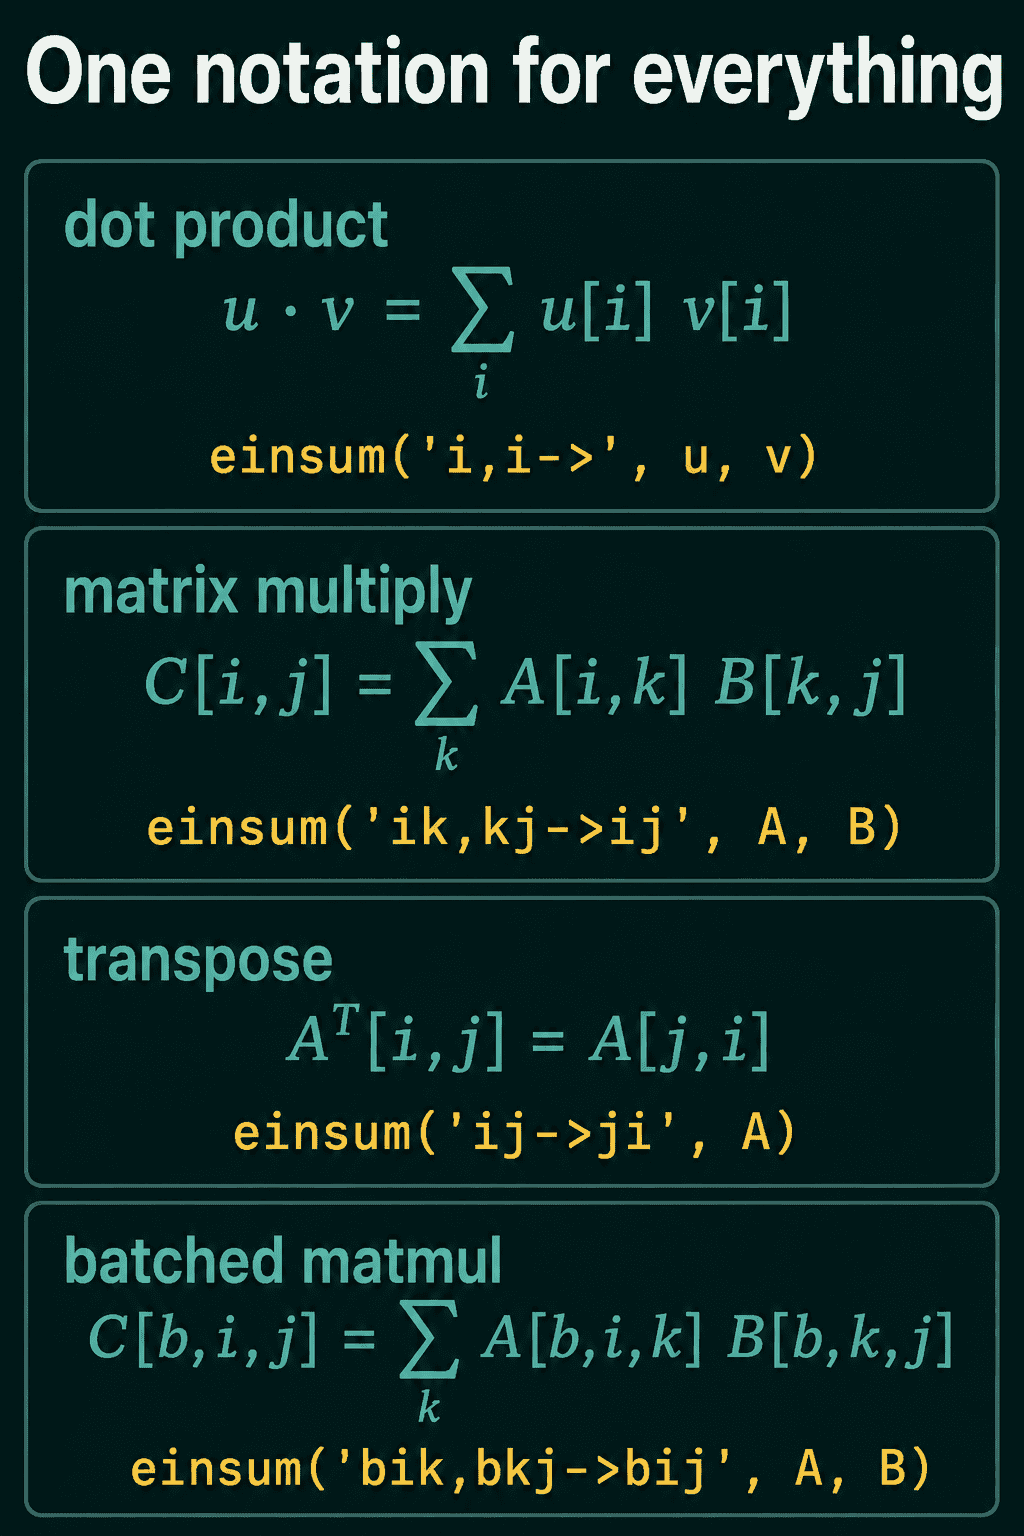
Take the dot product, torch.einsum('i,i->', u, v). Both vectors have one axis, and both call it i, so entry $i$ of u gets multiplied by entry $i$ of v. Nothing is written after the arrow, so i is summed away and the result is a single number. That is the formula for the dot product, where $u_i$ and $v_i$ are entry $i$ of each vector:
$$\mathbf{u} \cdot \mathbf{v} = \sum_i u_i v_i$$
The einsum string is close to a letter-for-letter copy of that formula: the shared index is i, and the empty output says the sum runs over it.
Matrix multiplication and transpose
For matrix multiplication, A has shape $(m, n)$ and B has shape $(n, p)$. Entry $(i, j)$ of the product $C$ multiplies row $i$ of $A$ against column $j$ of $B$ and adds up the products, where $k$ runs over the shared axis of size $n$:
$$C_{ij} = \sum_k A_{ik} B_{kj}$$
The einsum version labels A as ik, B as kj, and the output as ij: torch.einsum('ik,kj->ij', A, B). The letter k appears in both inputs and not in the output, so it is summed over, which matches the $\sum_k$ in the formula.
A transpose swaps rows and columns, and in einsum it is a relabelling with one input: torch.einsum('ij->ji', A). No letter is repeated and none is dropped, so nothing gets summed, and the output only lists the two axes in the opposite order.
Elementwise and outer products
The elementwise (Hadamard) product multiplies two same-shaped matrices position by position, $(A \circ B)_{ij} = A_{ij} B_{ij}$. In einsum both inputs are labelled ij and the output keeps ij: torch.einsum('ij,ij->ij', A, B). Every letter survives into the output, so nothing is summed.
The outer product of two vectors builds a matrix whose entry $(i, j)$ is $u_i v_j$. In torch.einsum('i,j->ij', u, v) the two inputs get different letters, so there is no shared letter to sum over. Both letters become axes of the result. A vector of length 3 and a vector of length 3 give a $3 \times 3$ matrix.
Here are all five, with the dot product and matrix product checked against the usual operator:
1import torch
2
3u = torch.tensor([1., 2., 3.])
4v = torch.tensor([4., 5., 6.])
5print(torch.einsum('i,i->', u, v))        # dot product
6print(u @ v)
7
8A = torch.tensor([[1., 2.], [3., 4.]])
9B = torch.tensor([[5., 6.], [7., 8.]])
10print(torch.einsum('ik,kj->ij', A, B))    # matrix multiplication
11print(torch.einsum('ij->ji', A))          # transpose
12print(torch.einsum('ij,ij->ij', A, B))    # elementwise product
13print(torch.einsum('i,j->ij', u, v)) # outer product1tensor(32.)
2tensor(32.)
3tensor([[19., 22.],
4 [43., 50.]])
5tensor([[1., 3.],
6 [2., 4.]])
7tensor([[ 5., 12.],
8 [21., 32.]])
9tensor([[ 4., 5., 6.],
10 [ 8., 10., 12.],
11 [12., 15., 18.]])The dot product is $1 \cdot 4 + 2 \cdot 5 + 3 \cdot 6 = 32$, the same from both calls. The matrix product's top-left entry is $1 \cdot 5 + 2 \cdot 7 = 19$, and the elementwise product's top-left entry is $1 \cdot 5 = 5$.
Batched matrix multiplication
A batch of matrices is a 3D tensor whose first axis indexes the matrices. Take 8 matrices of shape $(3, 4)$ in A and 8 of shape $(4, 5)$ in B. A batched matrix multiplication multiplies the first matrix of A with the first of B, then the second with the second, and so on. The formula is the matrix product with a batch index $b$ added to every term:
$$C_{bij} = \sum_k A_{bik} B_{bkj}$$
In einsum, the batch letter b appears in both inputs and also in the output, so it is kept as an axis instead of being summed: torch.einsum('bik,bkj->bij', A, B). Only k is summed.
1import torch
2
3torch.manual_seed(0)
4A = torch.randn(8, 3, 4)   # 8 matrices of shape (3, 4)
5B = torch.randn(8, 4, 5)   # 8 matrices of shape (4, 5)
6
7C = torch.einsum('bik,bkj->bij', A, B)
8print(C.shape)
9print(torch.allclose(C, A @ B))1torch.Size([8, 3, 5])
2TrueThe result has one $(3, 5)$ matrix per batch entry, and it matches A @ B, which also treats the first axis as a batch.
When to use einsum
For everyday code, @ and * cover matrix products and elementwise products directly, and they are shorter to write. Einsum is useful when reading code that already uses it, and when writing an operation over three or more axes where it is easy to lose track of which axis is multiplied against which. Writing the string first also documents the shapes: anyone reading 'bik,bkj->bij' can see that b is a batch axis and k is the axis that disappears.
Common mistakes
- A summed letter with two different sizes. Every use of a letter has to have the same size. Calling
torch.einsum('ik,kj->ij', A, B)withAandBboth of shape $(3, 4)$ fails, becausekis 4 inAand 3 inB, and PyTorch says so:
1import torch
2
3A = torch.randn(3, 4)
4B = torch.randn(3, 4)
5try:
6    torch.einsum('ik,kj->ij', A, B)
7except RuntimeError as e:
8 print(e)1einsum(): subscript k has size 3 for operand 1 which does not broadcast with previously seen size 4- Dropping a letter that should survive. Writing
'bik,bkj->ij'instead of'bik,bkj->bij'sums over the batch axis too, so the 8 matrix products get added into one $(3, 5)$ matrix with no error. - Swapping the output order.
'ik,kj->ji'gives the transpose of the matrix product, not the product. The output letters set the axis order of the result. - The wrong number of letters. Each input needs exactly one letter per axis, so a 3D tensor needs three letters.
Related math
The two operations einsum most often stands in for are covered in matrix multiplication explained and Hadamard product vs matrix multiplication. The single-number case is the dot product, and reading tensor shapes and axes is in what is a tensor?.
QuiddityML teaches einsum as a concept in the linear algebra part of the Math track, with exercises that match einsum calls to formulas and trace the shapes through 'bik,bkj->bij'. The last one is writing a matmul_einsum function from scratch.