By Sagi Shaier · 4 November 2026 · 8 min read
LSTM vs GRU
How a GRU's reset and update gates work by hand and in PyTorch code, how its parameter count compares with an LSTM's, and which of the two to start with.
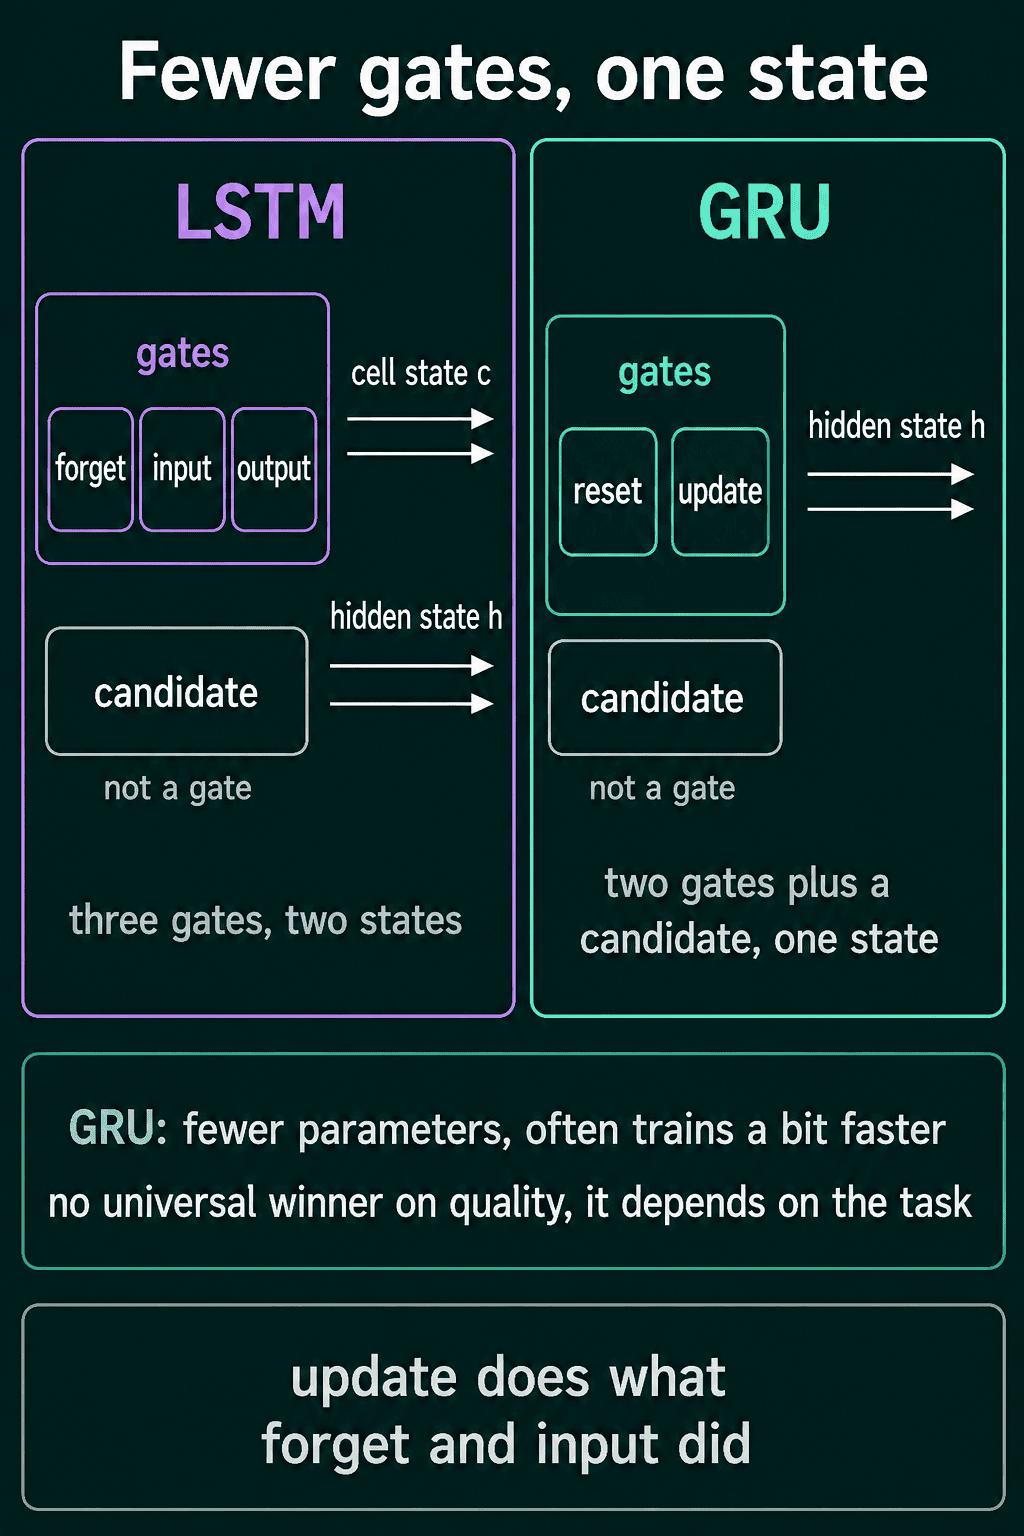
A Gated Recurrent Unit (GRU) is a recurrent neural network cell with two gates and one state vector. A Long Short-Term Memory cell (LSTM) has three gates and two state vectors. Both were designed to help a recurrent network keep information across many steps of a sequence, such as the tokens of a sentence, where a token is a whole word or a piece of a word.
What problem do gated cells solve?
A plain recurrent neural network (RNN) reads a sequence one step at a time and keeps one vector called the hidden state, written $\mathbf{h}_t$ at step $t$. At every step it rewrites the whole hidden state from the new input $\mathbf{x}_t$ and the old hidden state. The rewrite multiplies the old state by a learned weight matrix $\mathbf{W}_h$, multiplies the input by another learned matrix $\mathbf{W}_x$, adds a learned bias $\mathbf{b}$ and squashes the result with $\tanh$:
$$\mathbf{h}_t = \tanh(\mathbf{W}_h \mathbf{h}_{t-1} + \mathbf{W}_x \mathbf{x}_t + \mathbf{b})$$
During training, the gradient for a token far back in the sequence has to pass through every one of those rewrites. It usually shrinks at each one, so the network gets little signal from distant tokens and mostly learns short-range patterns. This is called the vanishing gradient problem.
Gated cells add gates, which are vectors of numbers between 0 and 1. A gate multiplies another vector entry by entry, written $\odot$. For example, $[0.6, -0.4] \odot [1, 0] = [0.6, 0]$, so the first entry passes through and the second is blocked. Gates get their range from the sigmoid function $\sigma$, which maps any number to a value between 0 and 1. With gates, a cell can keep part of its old state instead of rewriting all of it.
How an LSTM handles it
An LSTM carries two vectors from step to step. The hidden state $\mathbf{h}_t$ is what it outputs, and the cell state $\mathbf{c}_t$ is a separate memory. Three gates control the memory. The forget gate sets how much of the old cell state survives, the input gate sets how much new content gets written, and the output gate sets how much of the cell state shows up in $\mathbf{h}_t$. The new content itself is called the candidate, and it comes from a $\tanh$ layer. So an LSTM learns four projections at every step, one for each gate and one for the candidate. The LSTM post goes through those equations step by step.
How a GRU works
A GRU has the same goal with a smaller design. It has two gates and no separate cell state, so the hidden state is both the memory carried forward and the output:
- The reset gate $\mathbf{r}_t$ sets how much of the old hidden state to use when computing the candidate.
- The update gate $\mathbf{z}_t$ sets how far the hidden state moves from its old value toward the candidate.
- The candidate $\tilde{\mathbf{h}}_t$ is the proposed new hidden state. Like the LSTM's candidate, it comes from $\tanh$ and is not a gate.
The notation $[\mathbf{x}_t, \mathbf{h}_{t-1}]$ means the two vectors joined end to end. For example, $\mathbf{x}_t = [1, 2]$ and $\mathbf{h}_{t-1} = [0.6, -0.4]$ join into $[1, 2, 0.6, -0.4]$. Each gate has its own weight matrix $\mathbf{W}$ of shape (hidden_size, input_size + hidden_size) and its own bias $\mathbf{b}$. The two gates read the joined vector:
$$\mathbf{r}_t = \sigma(\mathbf{W}_r [\mathbf{x}_t, \mathbf{h}_{t-1}] + \mathbf{b}_r)$$
$$\mathbf{z}_t = \sigma(\mathbf{W}_z [\mathbf{x}_t, \mathbf{h}_{t-1}] + \mathbf{b}_z)$$
The candidate reads the input joined with a reset version of the old state, $\mathbf{r}_t \odot \mathbf{h}_{t-1}$:
$$\tilde{\mathbf{h}}_t = \tanh(\mathbf{W}_h [\mathbf{x}_t, \mathbf{r}_t \odot \mathbf{h}_{t-1}] + \mathbf{b}_h)$$
The new hidden state mixes the old state and the candidate, entry by entry:
$$\mathbf{h}_t = (1 - \mathbf{z}_t) \odot \mathbf{h}_{t-1} + \mathbf{z}_t \odot \tilde{\mathbf{h}}_t$$
Where an entry of $\mathbf{z}_t$ is 0, the old hidden state stays as it was. Where it is 1, the candidate replaces it. The update gate covers what the LSTM's forget gate and input gate do separately, because the same $\mathbf{z}_t$ sets how much of the candidate comes in and $1 - \mathbf{z}_t$ sets how much of the old state stays.
One update by hand
Take a hidden size of 2 with the old hidden state $\mathbf{h}_{t-1} = [0.6, -0.4]$.
Suppose the reset gate comes out as $\mathbf{r}_t = [1, 0]$. The candidate then reads $\mathbf{r}_t \odot \mathbf{h}_{t-1} = [0.6, 0]$, so it uses the first entry of the old state and ignores the second. Suppose the candidate comes out as $\tilde{\mathbf{h}}_t = [0.5, 0.3]$ and the update gate as $\mathbf{z}_t = [0.1, 0.9]$.
In the first entry, $1 - 0.1 = 0.9$ of the old 0.6 stays and 0.1 of the candidate's 0.5 comes in, giving $0.54 + 0.05 = 0.59$. In the second entry, 0.1 of the old $-0.4$ stays and 0.9 of the candidate's 0.3 comes in, giving $-0.04 + 0.27 = 0.23$:
$$\mathbf{h}_t = [0.59, 0.23]$$
The first entry kept most of its old value, and the second was mostly replaced. The same update in PyTorch:
1import torch
2
3h_prev = torch.tensor([0.6, -0.4])
4z = torch.tensor([0.1, 0.9])         # update gate
5h_tilde = torch.tensor([0.5, 0.3])   # candidate
6
7h = (1 - z) * h_prev + z * h_tilde
8print(h)1tensor([0.5900, 0.2300])Coding a GRU cell from scratch
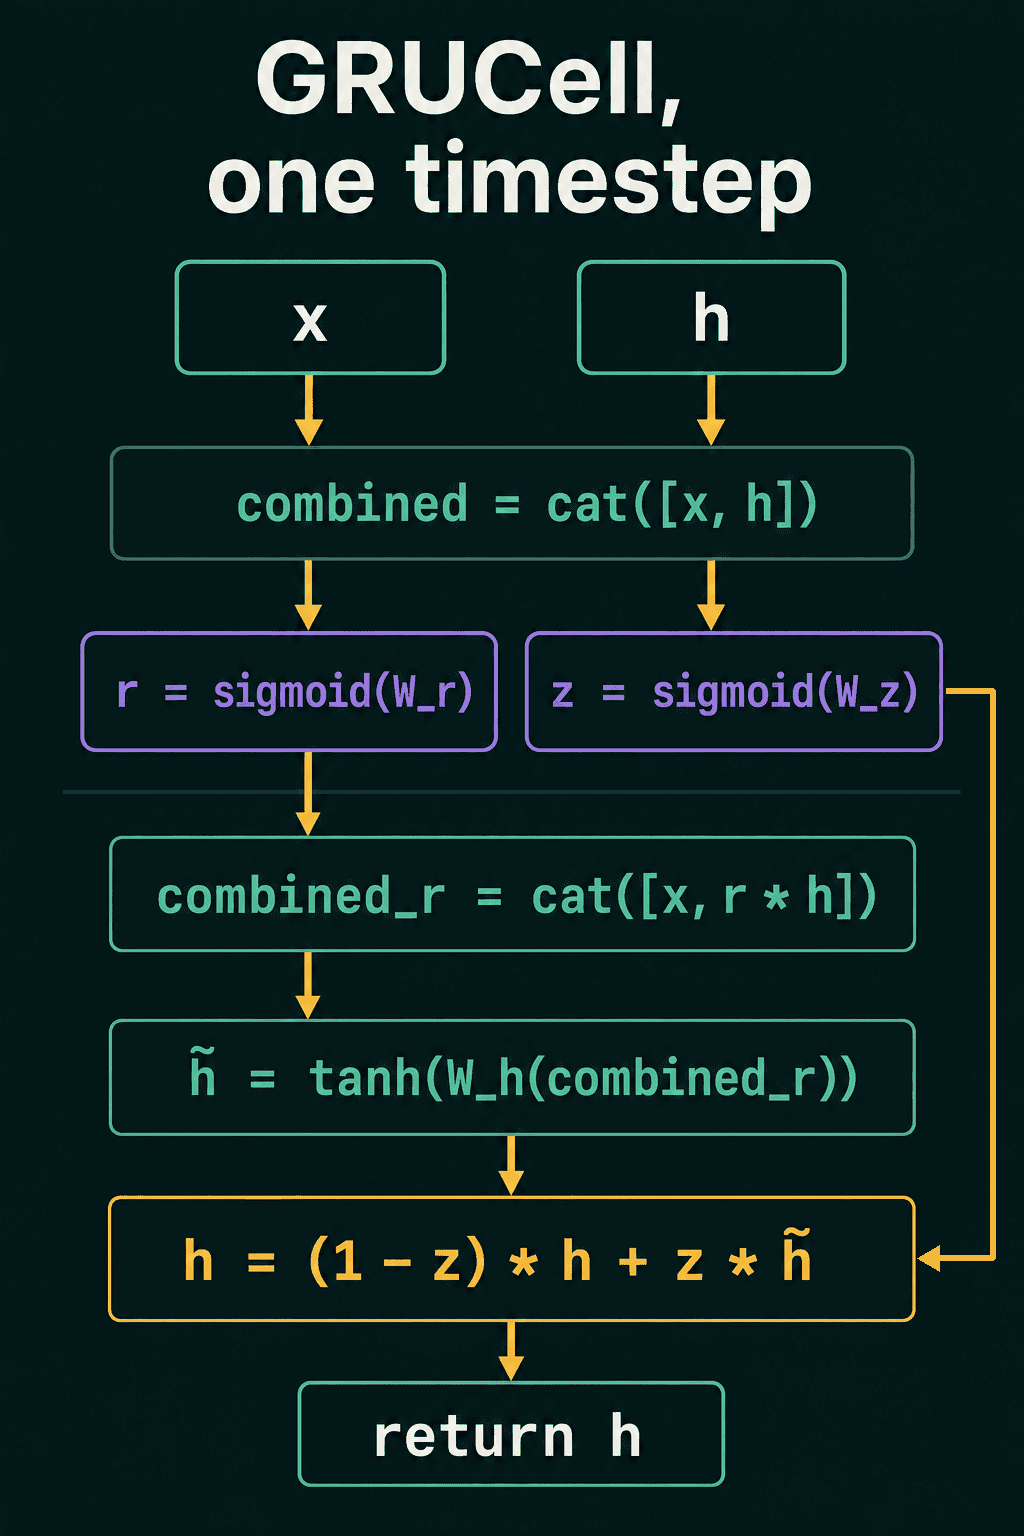
GRUCell turns the equations into one step of code. It takes the current input and the previous hidden state, then returns the new hidden state:
1import torch
2import torch.nn as nn
3
4class GRUCell(nn.Module):
5    def __init__(self, input_size, hidden_size):
6        super().__init__()
7        self.W_r = nn.Linear(input_size + hidden_size, hidden_size)
8        self.W_z = nn.Linear(input_size + hidden_size, hidden_size)
9        self.W_h = nn.Linear(input_size + hidden_size, hidden_size)
10
11    def forward(self, x, h):
12        combined = torch.cat([x, h], dim=1)
13        r = torch.sigmoid(self.W_r(combined))
14        z = torch.sigmoid(self.W_z(combined))
15        combined_r = torch.cat([x, r * h], dim=1)
16        h_tilde = torch.tanh(self.W_h(combined_r))
17        h = (1 - z) * h + z * h_tilde
18        return h
The two gates read combined, the input joined with the old state. The candidate reads combined_r, because the reset gate scales the old hidden state before the candidate is computed.
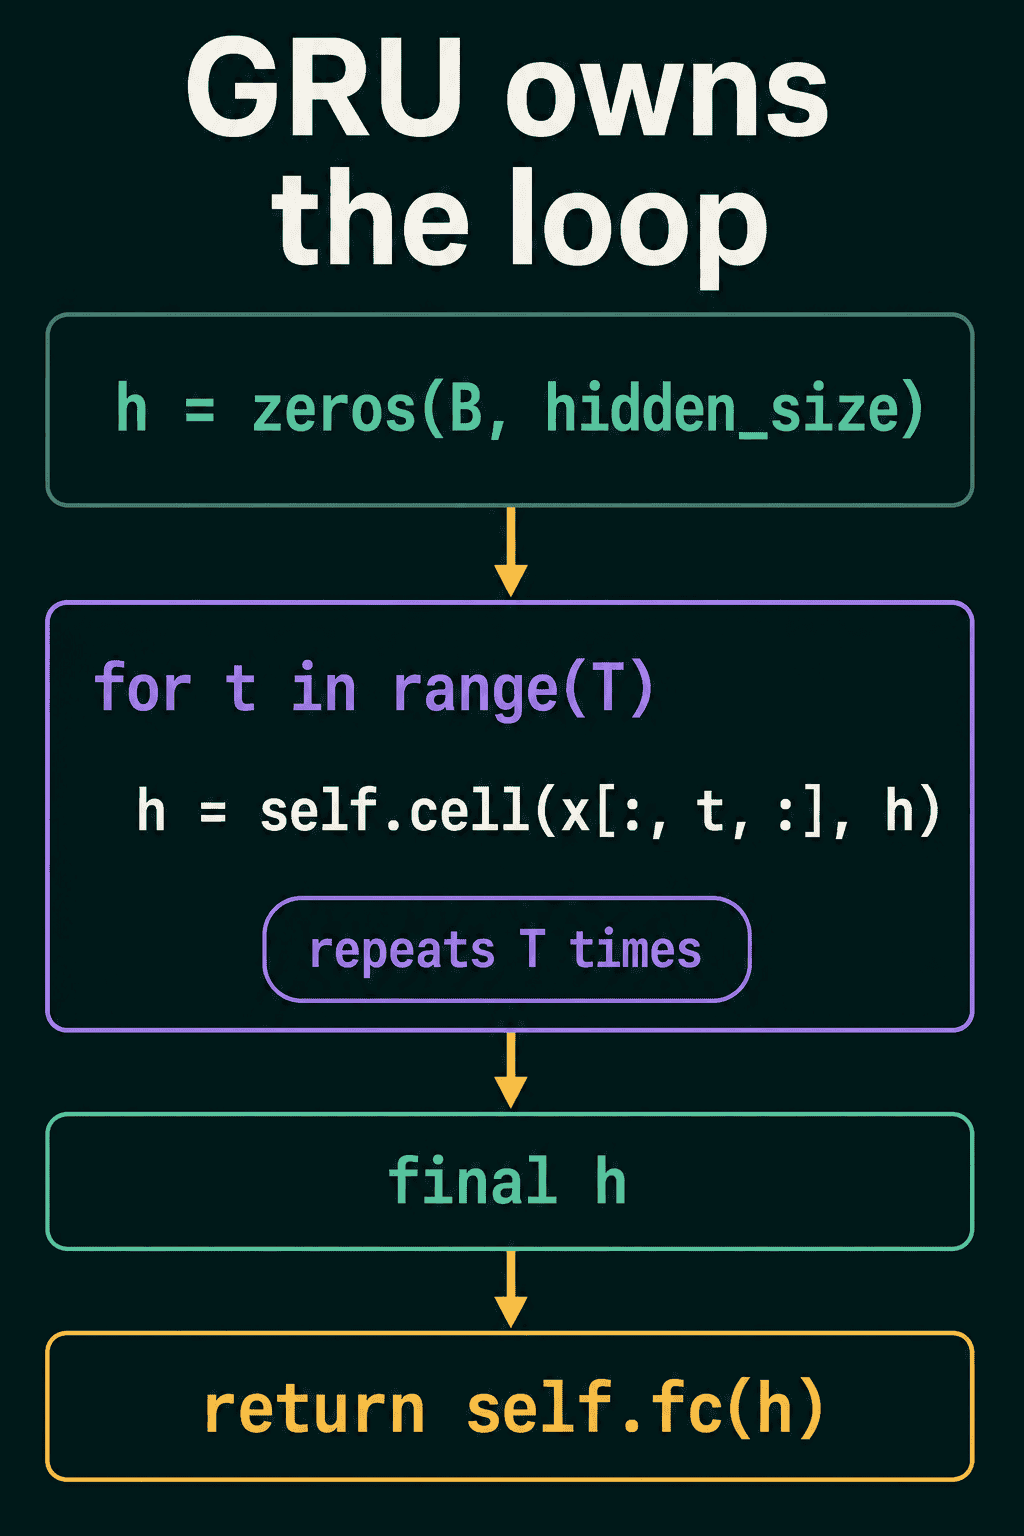
An outer model owns the starting state, the loop over steps and a classifier head:
1class GRU(nn.Module):
2    def __init__(self, input_size, hidden_size, num_classes):
3        super().__init__()
4        self.hidden_size = hidden_size
5        self.cell = GRUCell(input_size, hidden_size)
6        self.fc = nn.Linear(hidden_size, num_classes)
7
8    def forward(self, x):
9        B, T, _ = x.shape
10        h = torch.zeros(B, self.hidden_size, device=x.device)
11        for t in range(T):
12            h = self.cell(x[:, t, :], h)
13        return self.fc(h)
14
15torch.manual_seed(0)
16model = GRU(input_size=8, hidden_size=16, num_classes=3)
17x = torch.randn(4, 10, 8)  # 4 sequences, 10 steps, 8 numbers per step
18print(model(x).shape)1torch.Size([4, 3])Compared with an LSTM model, the loop carries one state instead of two. The classifier reads the final hidden state, which is called a many-to-one setup because many inputs produce one output.
nn.GRU in PyTorch
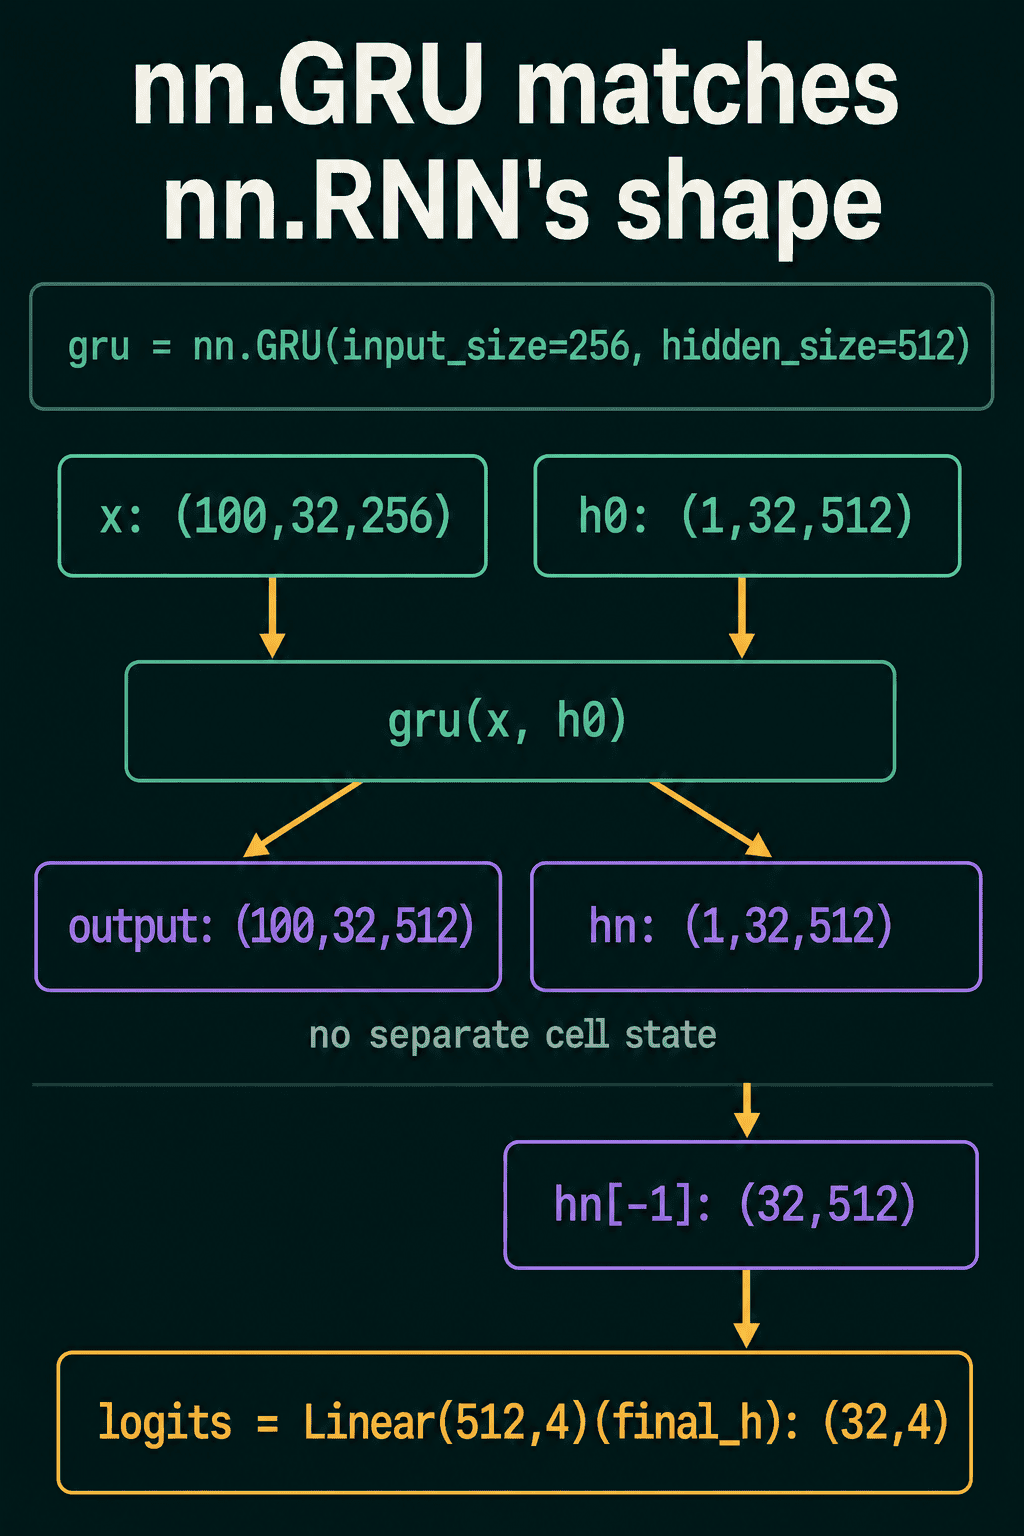
PyTorch has the recurrent layer built in as nn.GRU, so real code usually does not write the gates by hand. The interface matches nn.RNN, and a GRU returns output, hn. This example leaves batch_first at its default of False, so the input is laid out as (steps, batch, features):
1import torch
2import torch.nn as nn
3
4gru = nn.GRU(input_size=256, hidden_size=512)
5x = torch.randn(100, 32, 256)  # 100 steps, 32 sequences, 256 numbers per step
6h0 = torch.zeros(1, 32, 512)
7
8output, hn = gru(x, h0)
9final_h = hn[-1]
10logits = nn.Linear(512, 4)(final_h)
11
12print(output.shape)
13print(hn.shape)
14print(logits.shape)1torch.Size([100, 32, 512])
2torch.Size([1, 32, 512])
3torch.Size([32, 4])output has one hidden state per step, with shape (steps, batch, hidden size). The first dimension of hn counts layers, so hn[-1] is the last layer's final hidden state with shape (batch, hidden size), ready for a classifier. There is no cn, because a GRU has no cell state.
How many parameters each one has
An LSTM learns four projections per step, three gates and the candidate. A GRU learns three, two gates and the candidate. At the same hidden size the GRU has three quarters of the LSTM's parameters:
1import torch.nn as nn
2
3lstm = nn.LSTM(input_size=256, hidden_size=512)
4gru = nn.GRU(input_size=256, hidden_size=512)
5
6count = lambda m: sum(p.numel() for p in m.parameters())
7print(count(lstm), count(gru), count(gru) / count(lstm))11576960 1182720 0.75You can check these counts by hand. In PyTorch each projection has $512 \times 256$ input weights, $512 \times 512$ hidden weights and two bias vectors of length 512. That is 394,240 numbers per projection, so four projections give 1,576,960 and three give 1,182,720.
When to use which
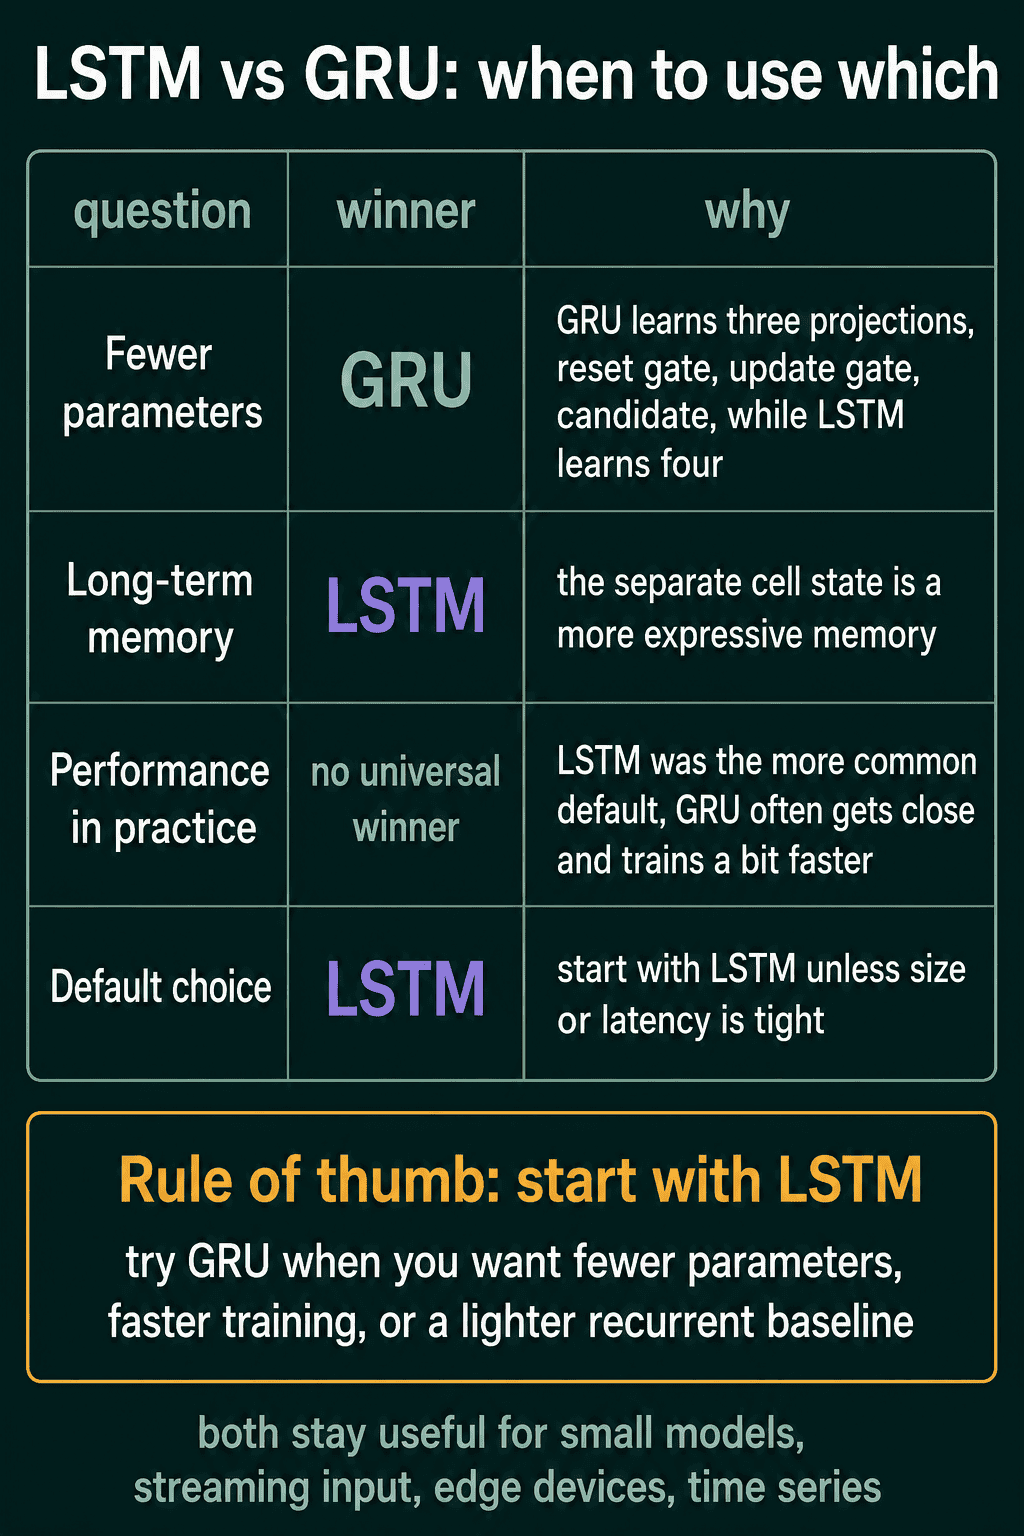
| Question | Winner | Why |
|---|---|---|
| Fewer parameters | GRU | three projections instead of four |
| Long-term memory | LSTM | a separate cell state |
| Results in practice | no universal winner | depends on the task |
| Default choice | LSTM | unless size or speed is tight |
In classic recurrent NLP, LSTMs were the more common default. GRUs are a smaller alternative, and on some sequence tasks they get close to LSTM results while training a bit faster. If you are using a recurrent model and have no tight limit on size or latency, start with an LSTM. Try a GRU when you want fewer parameters, faster training or a lighter recurrent baseline. Since neither one wins on every task, a fair way to choose is to train both and compare them on validation data.
In modern NLP, both cells are much less central than transformers. They are still used for small models, streaming input, devices with little memory and time-series data. The reason is cost. Attention compares every pair of positions in a sequence, while a recurrent model processes the sequence with a fixed-size state. Where the costs cross over depends on the model and the hardware, so there is no single sequence length at which one becomes cheaper.
Common mistakes
- Unpacking
nn.GRUlikenn.LSTM.output, (hn, cn) = gru(x)raises aValueError, because a GRU returns one state tensor and no cell state. - Passing (batch, steps, features) without
batch_first=True. The GRU runs without an error and treats the batch dimension as time. Withxof shape (32, 100, 256),hncomes out as (1, 100, 512) instead of (1, 32, 512). - Applying the reset gate in the wrong place. The reset gate scales the old hidden state only inside the candidate's input. The two gates read the plain joined vector.
- Flipping the update rule. In the form used here, $\mathbf{z}_t = 1$ takes the candidate and $\mathbf{z}_t = 0$ keeps the old state. Writing $\mathbf{z}_t \odot \mathbf{h}_{t-1} + (1 - \mathbf{z}_t) \odot \tilde{\mathbf{h}}_t$ in one place and the other form somewhere else mixes up what $\mathbf{z}_t$ means.
Related concepts
The RNN post covers the plain recurrent update and why its gradients vanish. The LSTM post goes through the LSTM's gates by hand and shows why its cell state helps gradients reach further back. In an encoder-decoder model, either cell can be the encoder that reads the input and the decoder that writes the output.
QuiddityML teaches the GRU and the LSTM vs GRU choice in the language models unit of its NLP track. Its GRU exercises include picking the code that computes the reset and update gates, spotting the bug in a GRUCell and writing the cell from scratch (QuiddityML).