NLP
From text and tokenization to embeddings, transformers, and LLMs. Posts are listed in the order the ideas build on each other.
What NLP is
 What NLP is
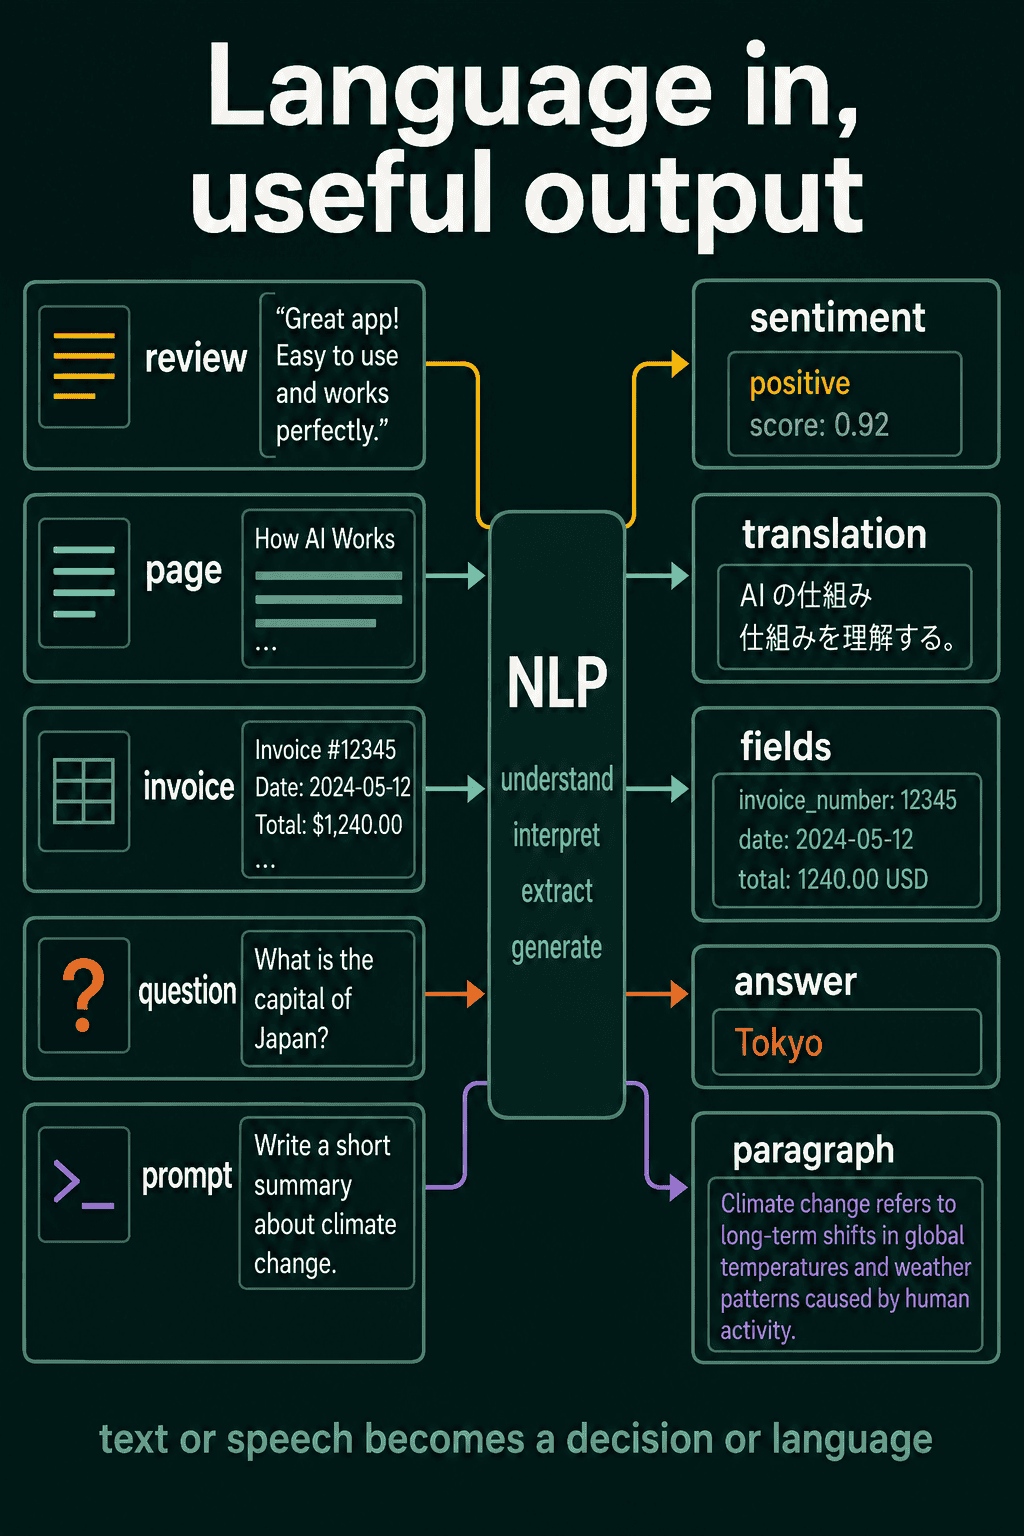
What is NLP? Natural language processing explained
The main NLP tasks from sentiment analysis to language modeling, the kinds of ambiguity that make human language hard for a computer, and why modern NLP learns from data instead of following hand-written rules.
 What NLP is
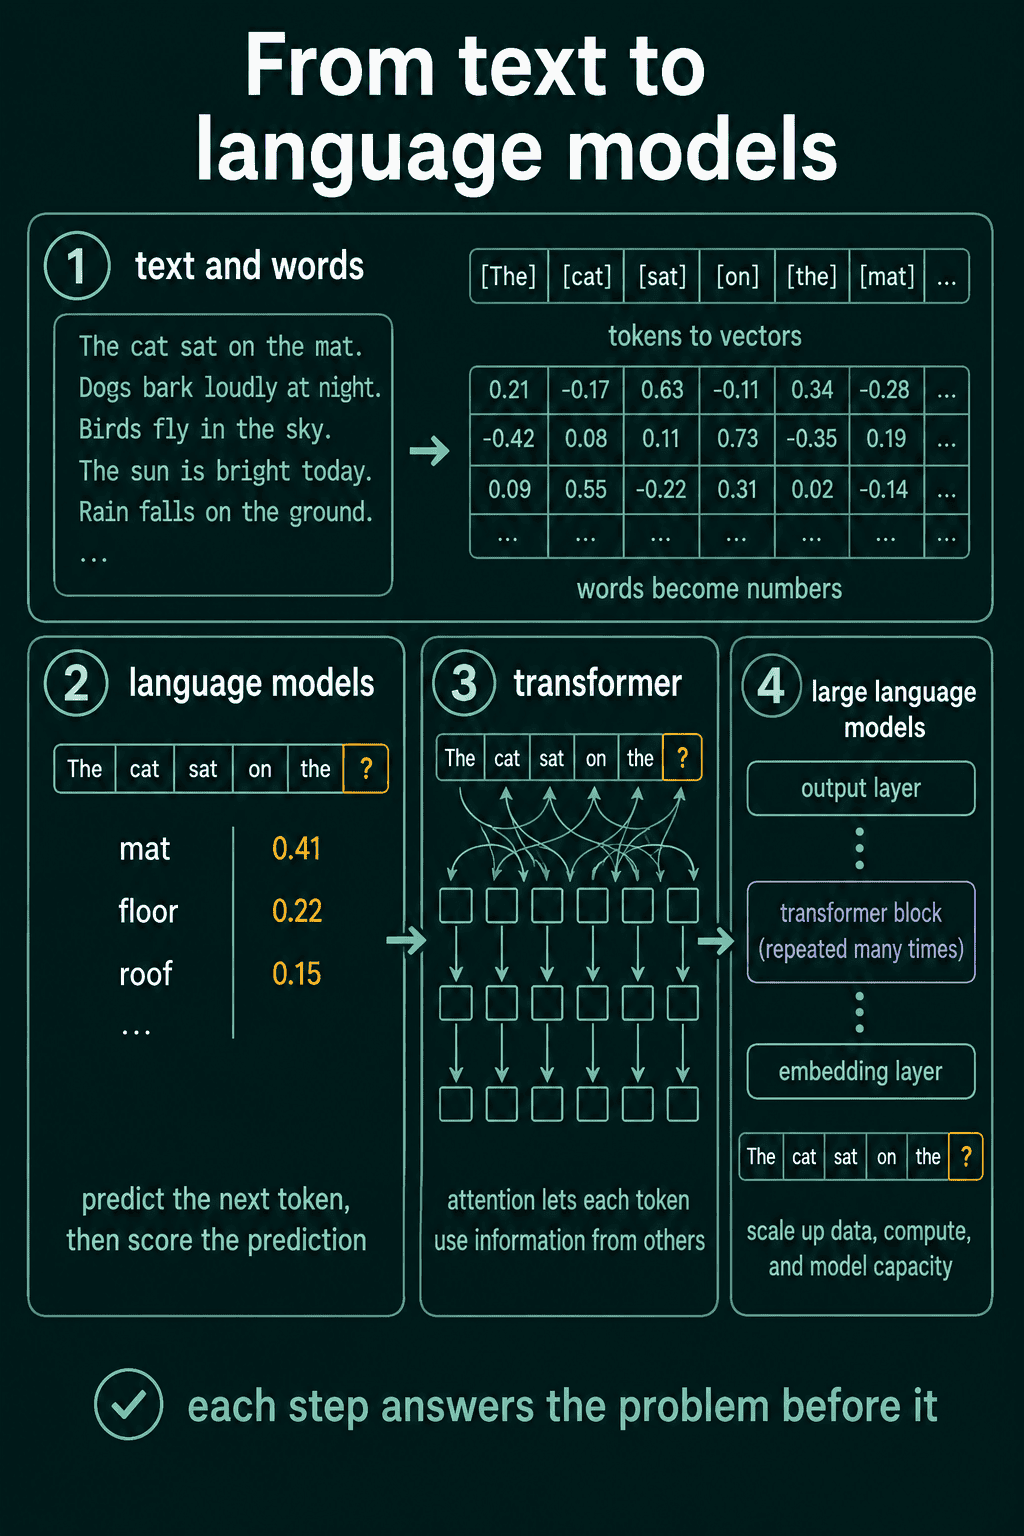
How to learn NLP in 2026: a complete roadmap from text to LLMs
What to learn for natural language processing and in what order, from tokenization and word embeddings to transformers, LLMs and post-training, so you can see what is ahead and check off what you already know.
 What NLP is
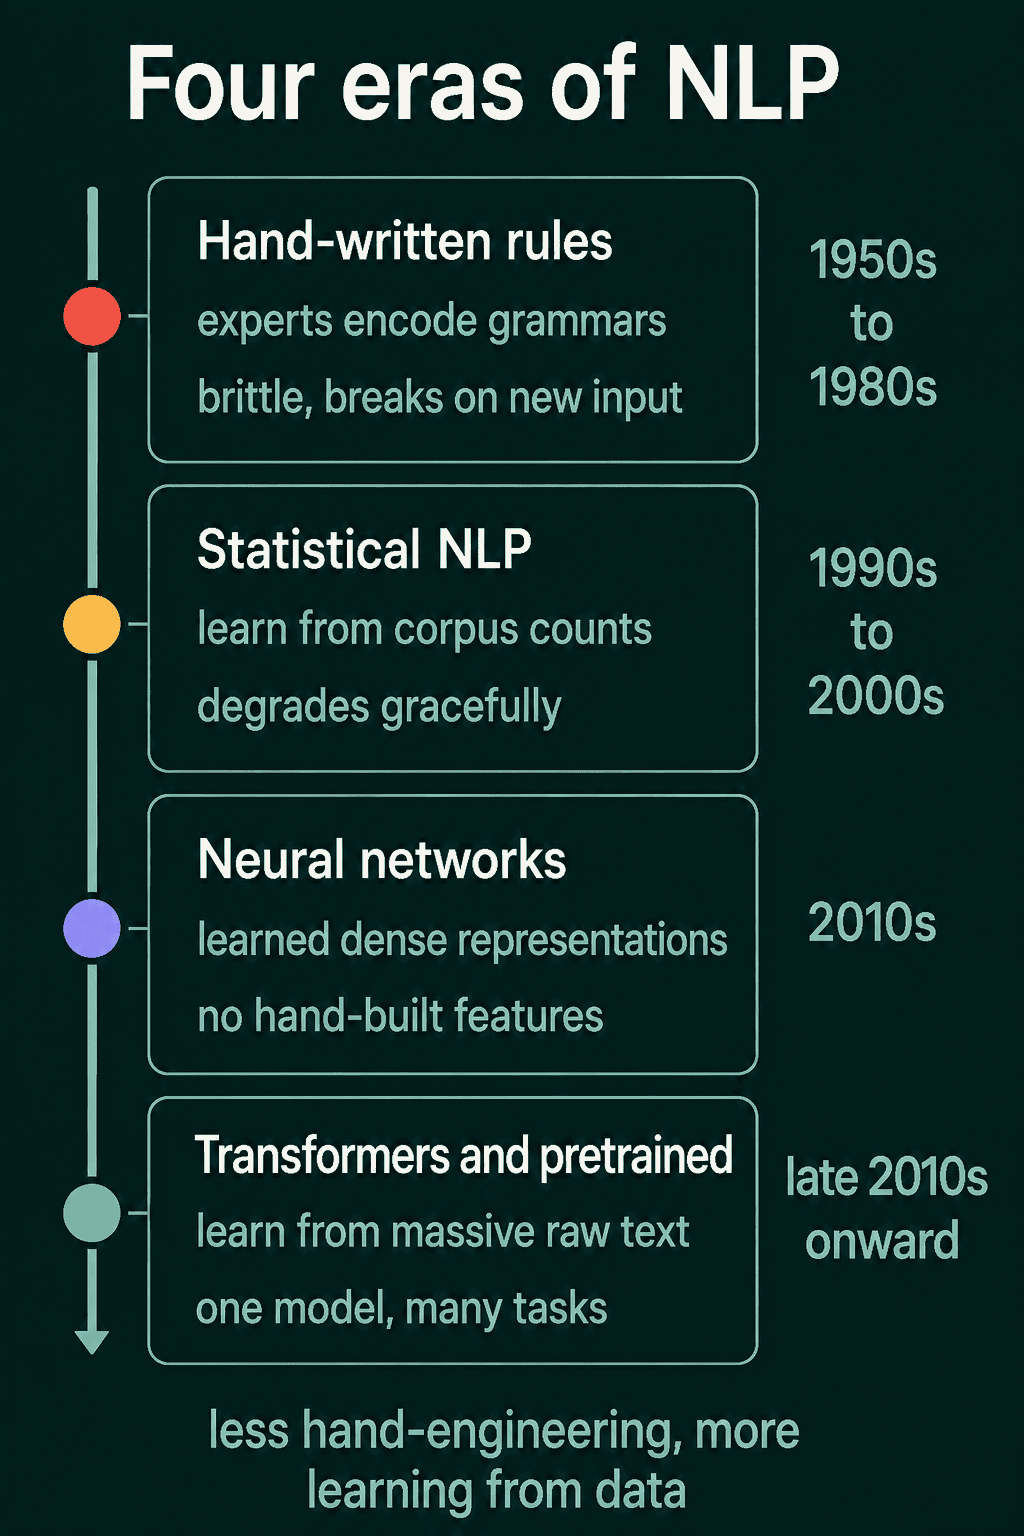
A short history of NLP: from ELIZA to deep learning
The four eras NLP went through on its way to today's large models, why each shift happened, and what the 1960s chatbot ELIZA shows about sounding smart without understanding anything.
Text as data
 Text as data
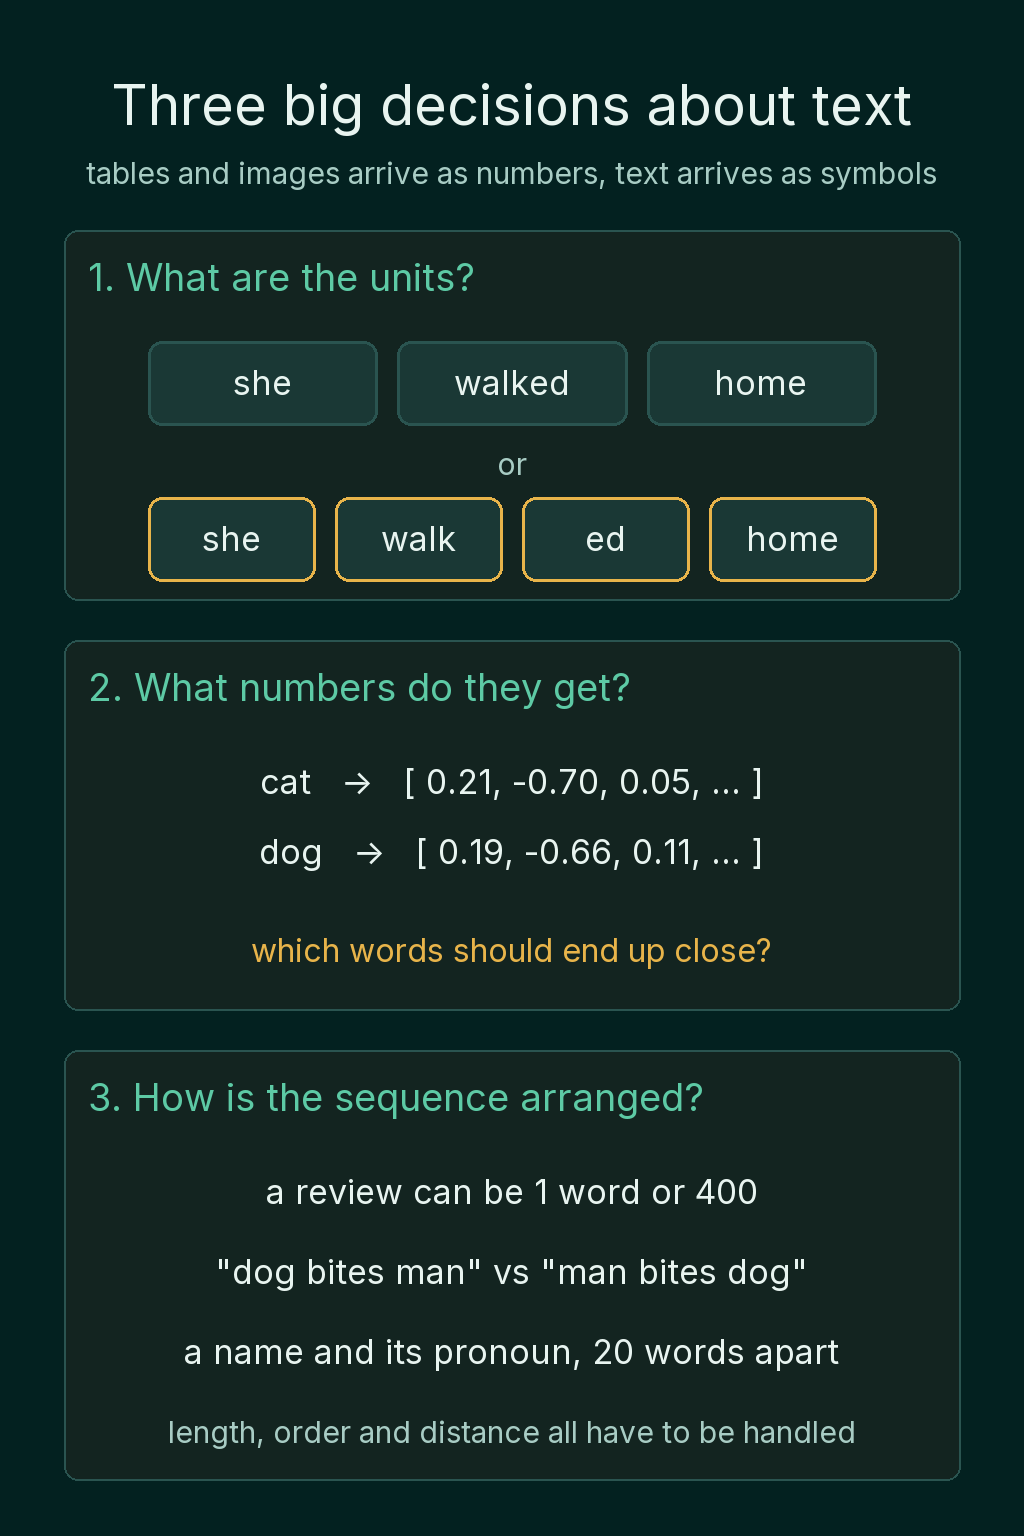
Why text is hard data for machine learning
How raw text differs from tables and images, and the three decisions an NLP system has to make before a model can learn anything from it.
 Text as data
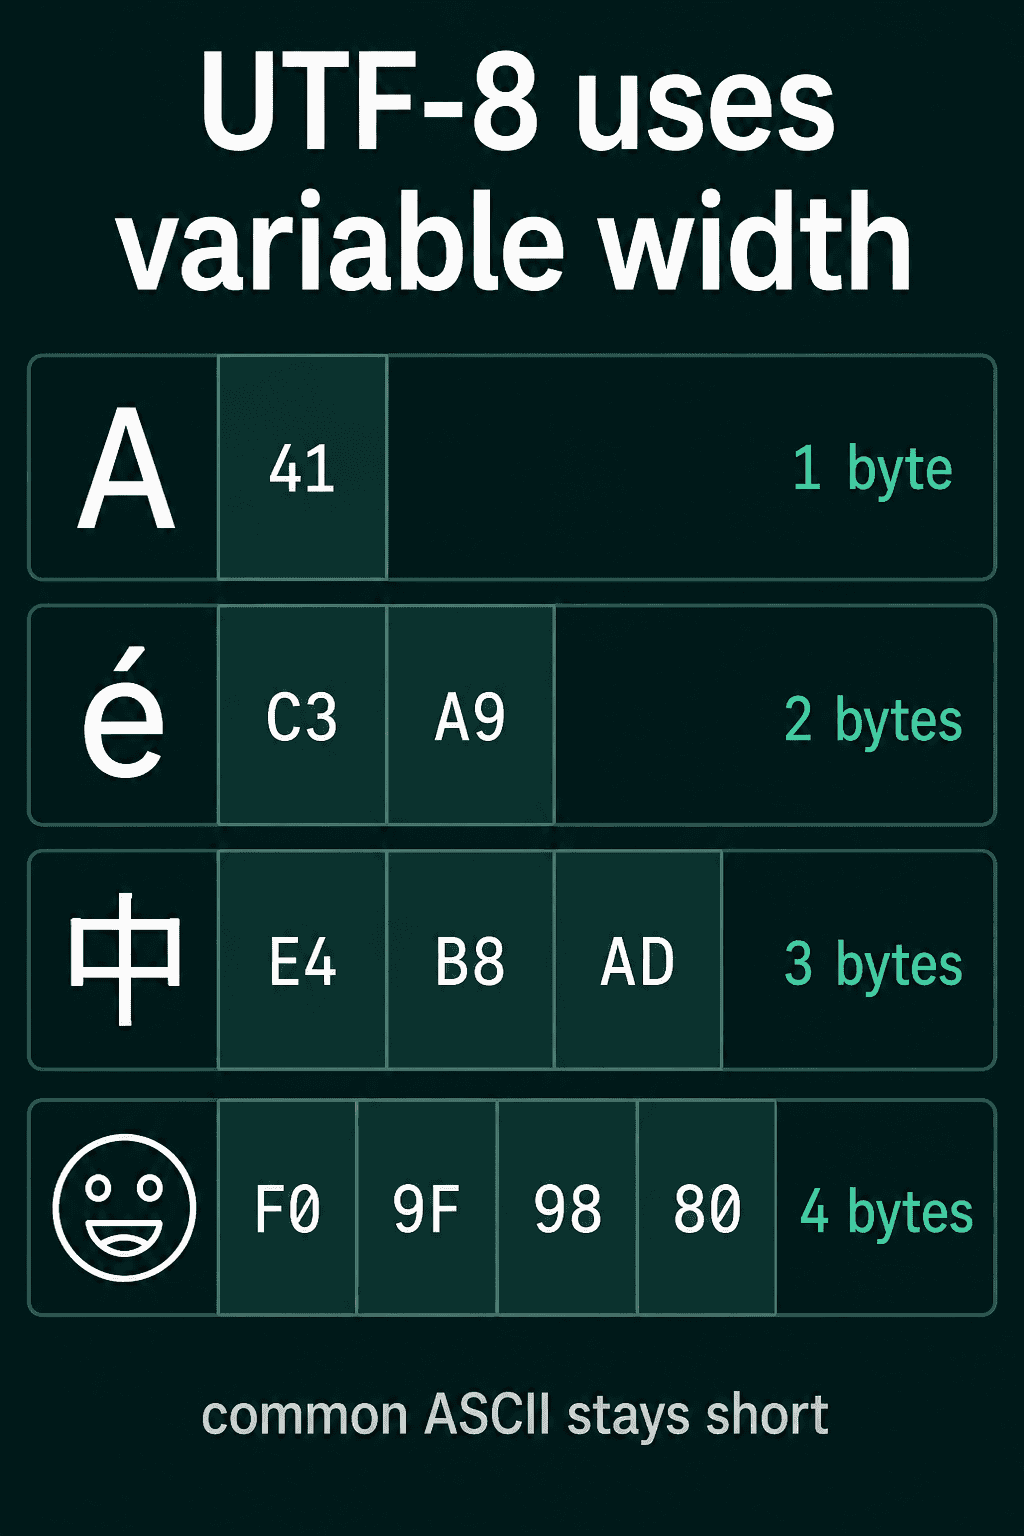
Unicode and UTF-8 explained: how computers store text
How a character becomes a code point and then bytes, why the same word can take a different number of bytes in different scripts, and how to fix text that compares wrong or shows up garbled.
 Text as data
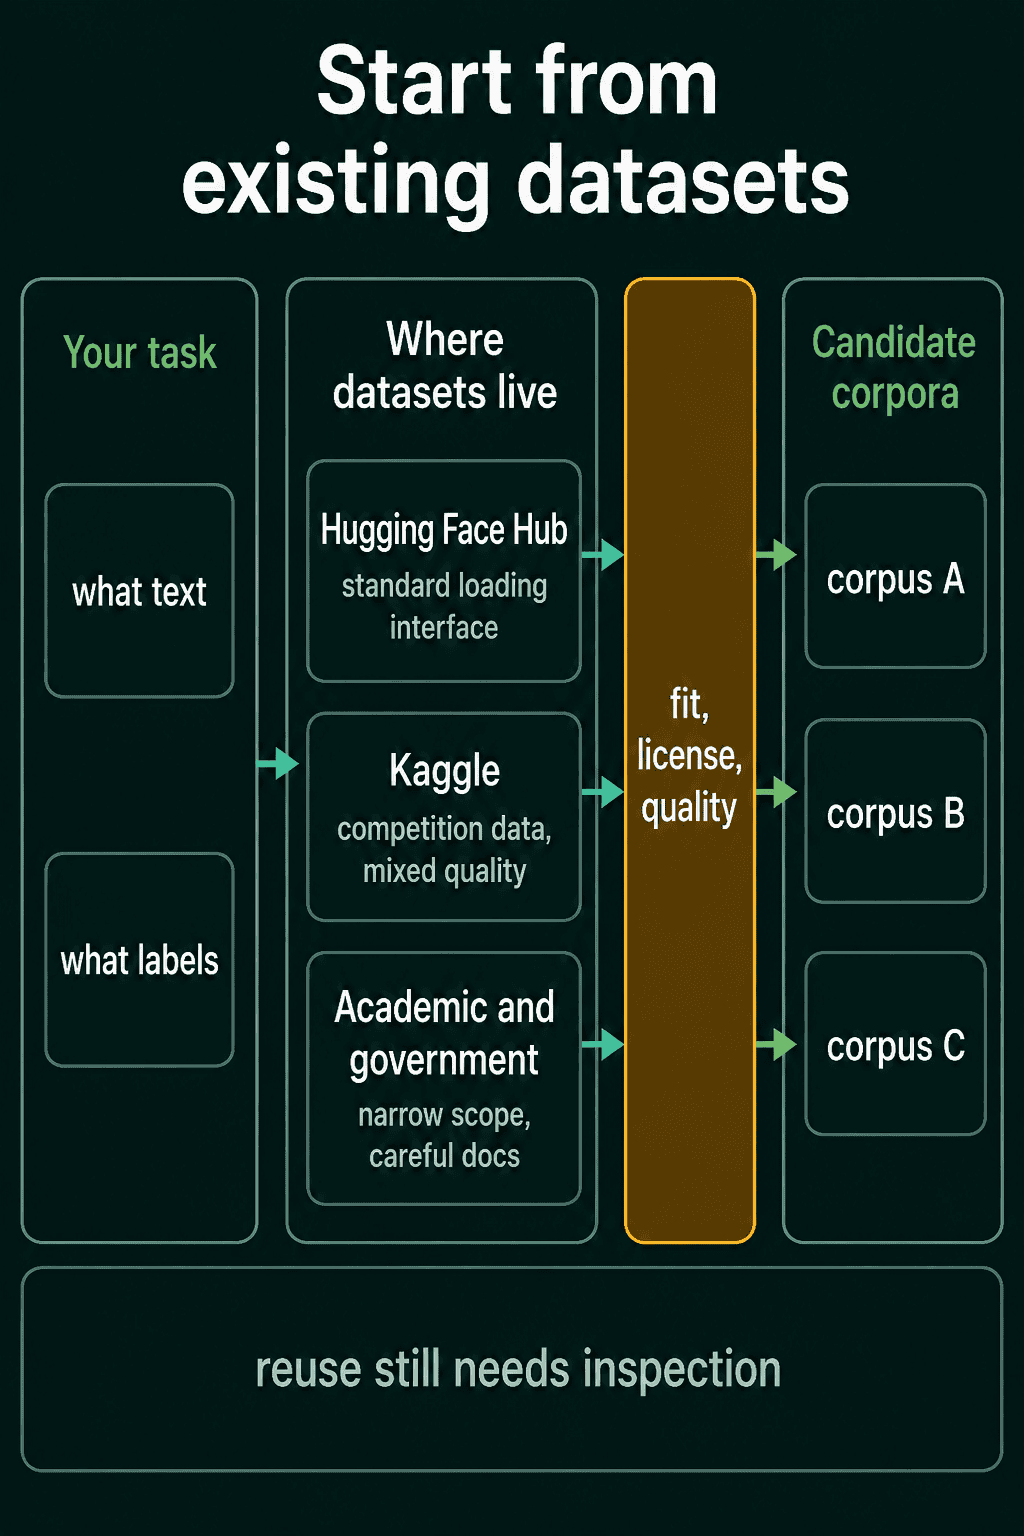
Where to find NLP datasets: Hugging Face Hub, Kaggle, and more
Which places to search for a text dataset, how to load one in Python, and what to check before you train anything on it.
 Text as data
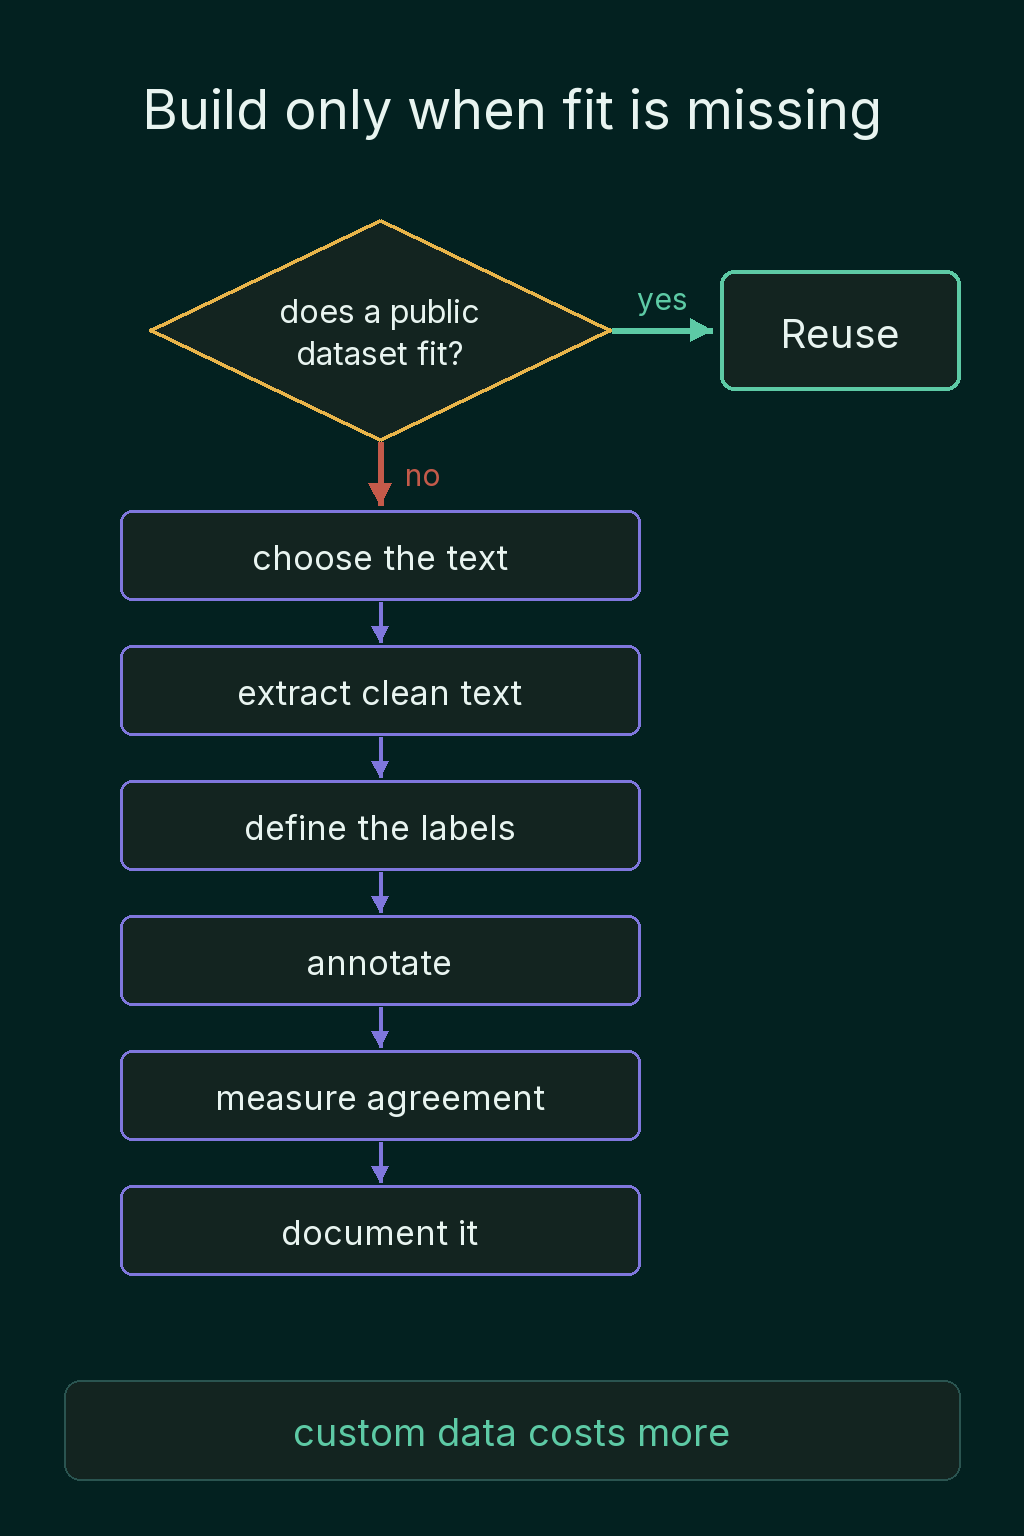
How to build your own NLP dataset: selecting data, extracting text, documenting it
How to choose the text for a custom dataset and pull clean text out of web pages, PDFs and scans, plus what to write down so the next person can trust it.
 Text as data
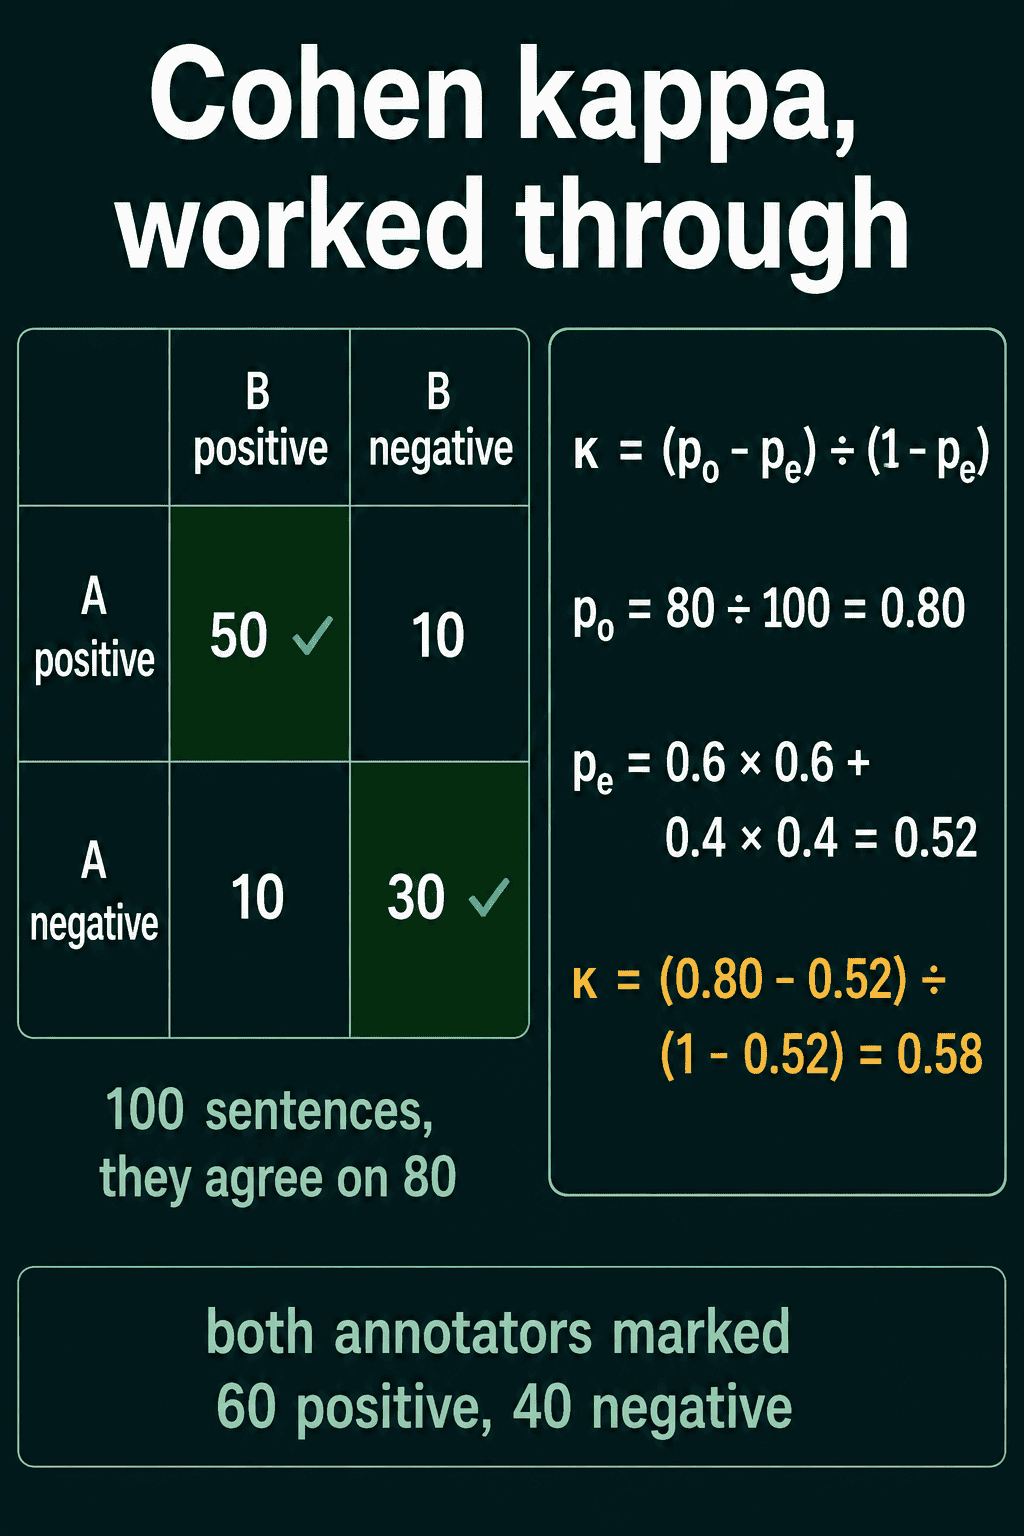
Data annotation for NLP: crowdsourcing vs experts, and inter-annotator agreement
How to design labels people can apply consistently, when to pay a crowd and when to hire experts, and how to compute Cohen's kappa to check whether your labels can be trusted.
 Text as data
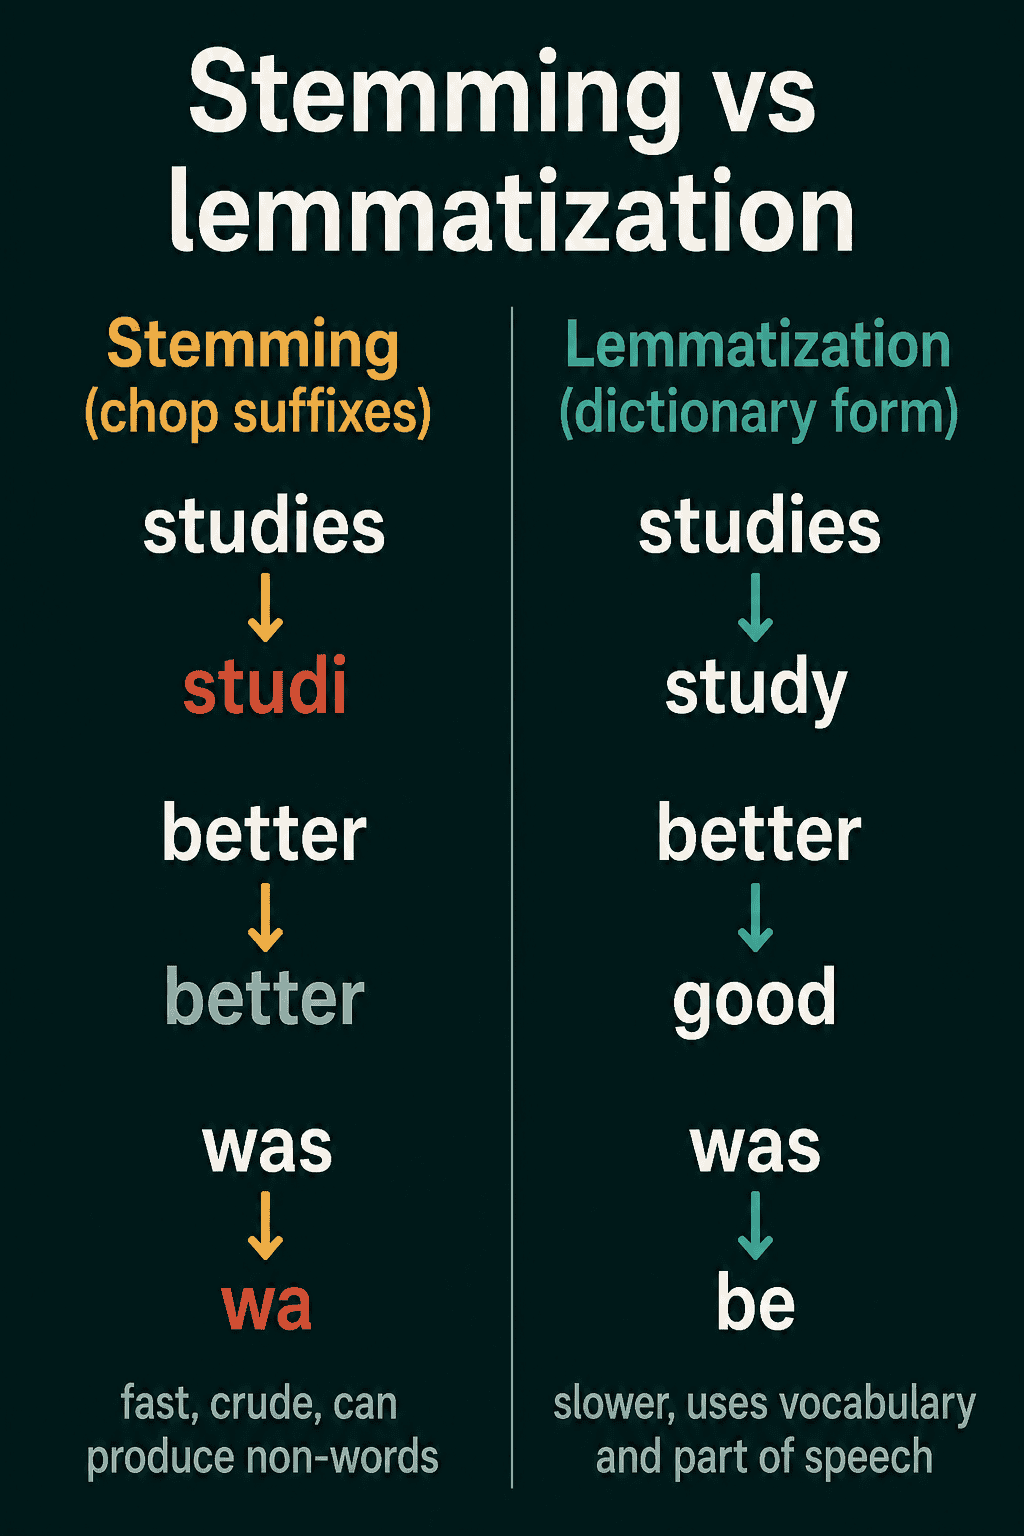
Text preprocessing in NLP: normalization, stemming vs lemmatization, and stopwords
What each classic cleanup step does to a sentence, with runnable NLTK code, where each one erases something a model could use, and how much of it to apply for a count-based model versus a transformer.
 Text as data
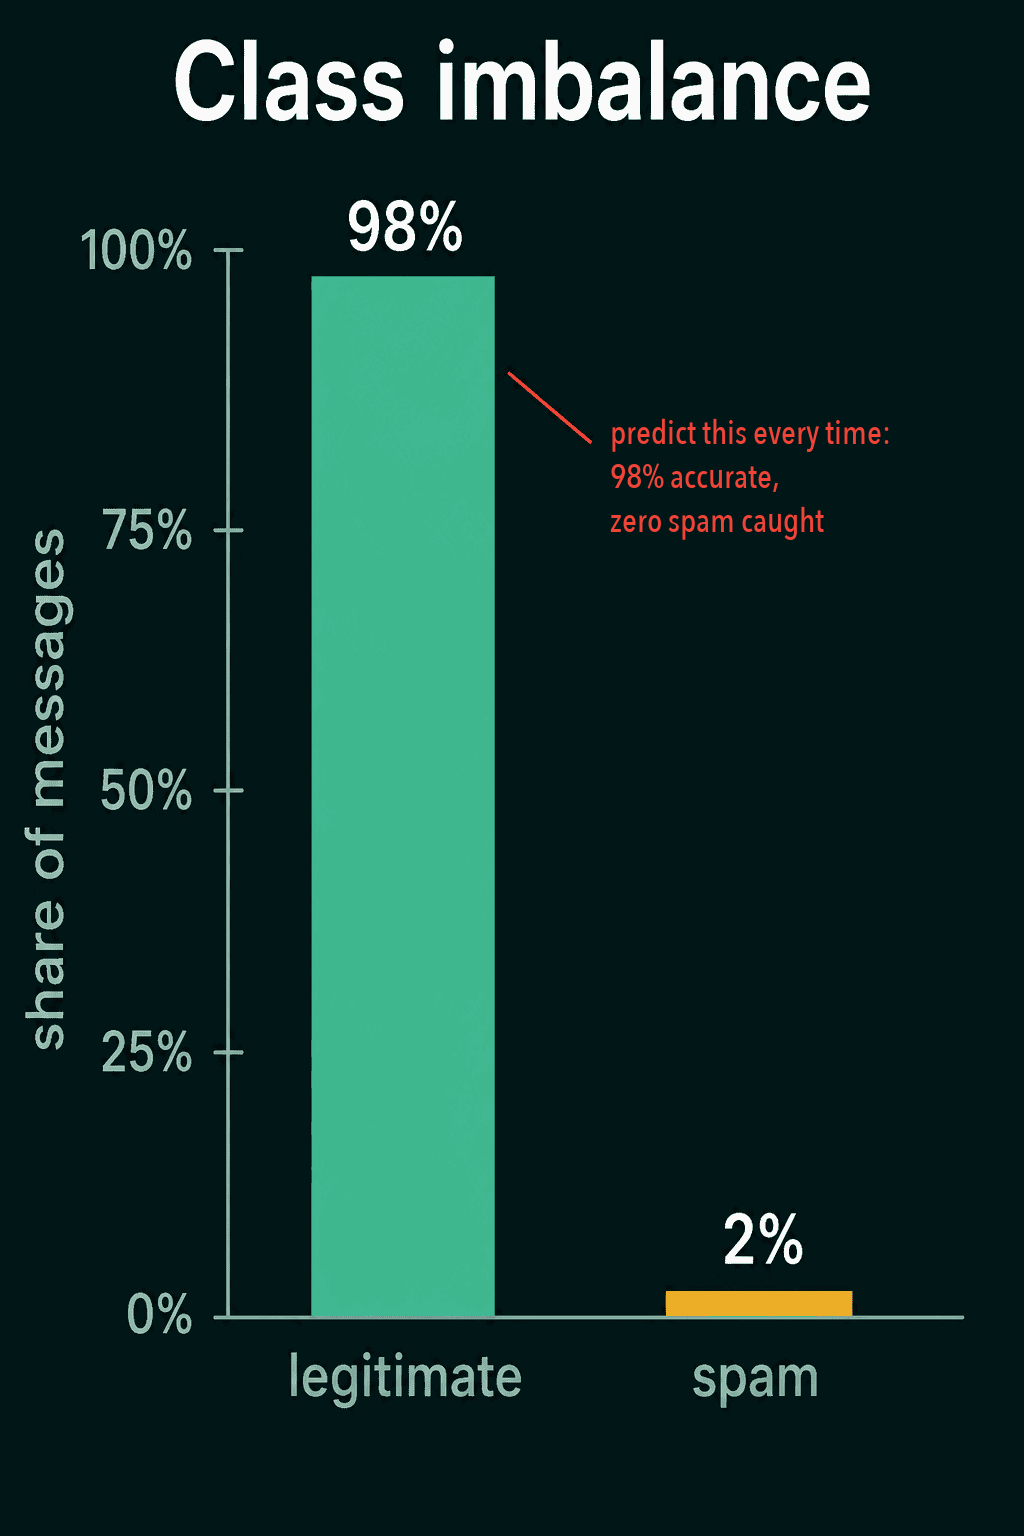
How to handle class imbalance in text classification
Why a spam filter can score 98% accuracy while catching no spam, which numbers to report instead, and how reweighting, oversampling and undersampling work in PyTorch, with what each one costs.
 Text as data
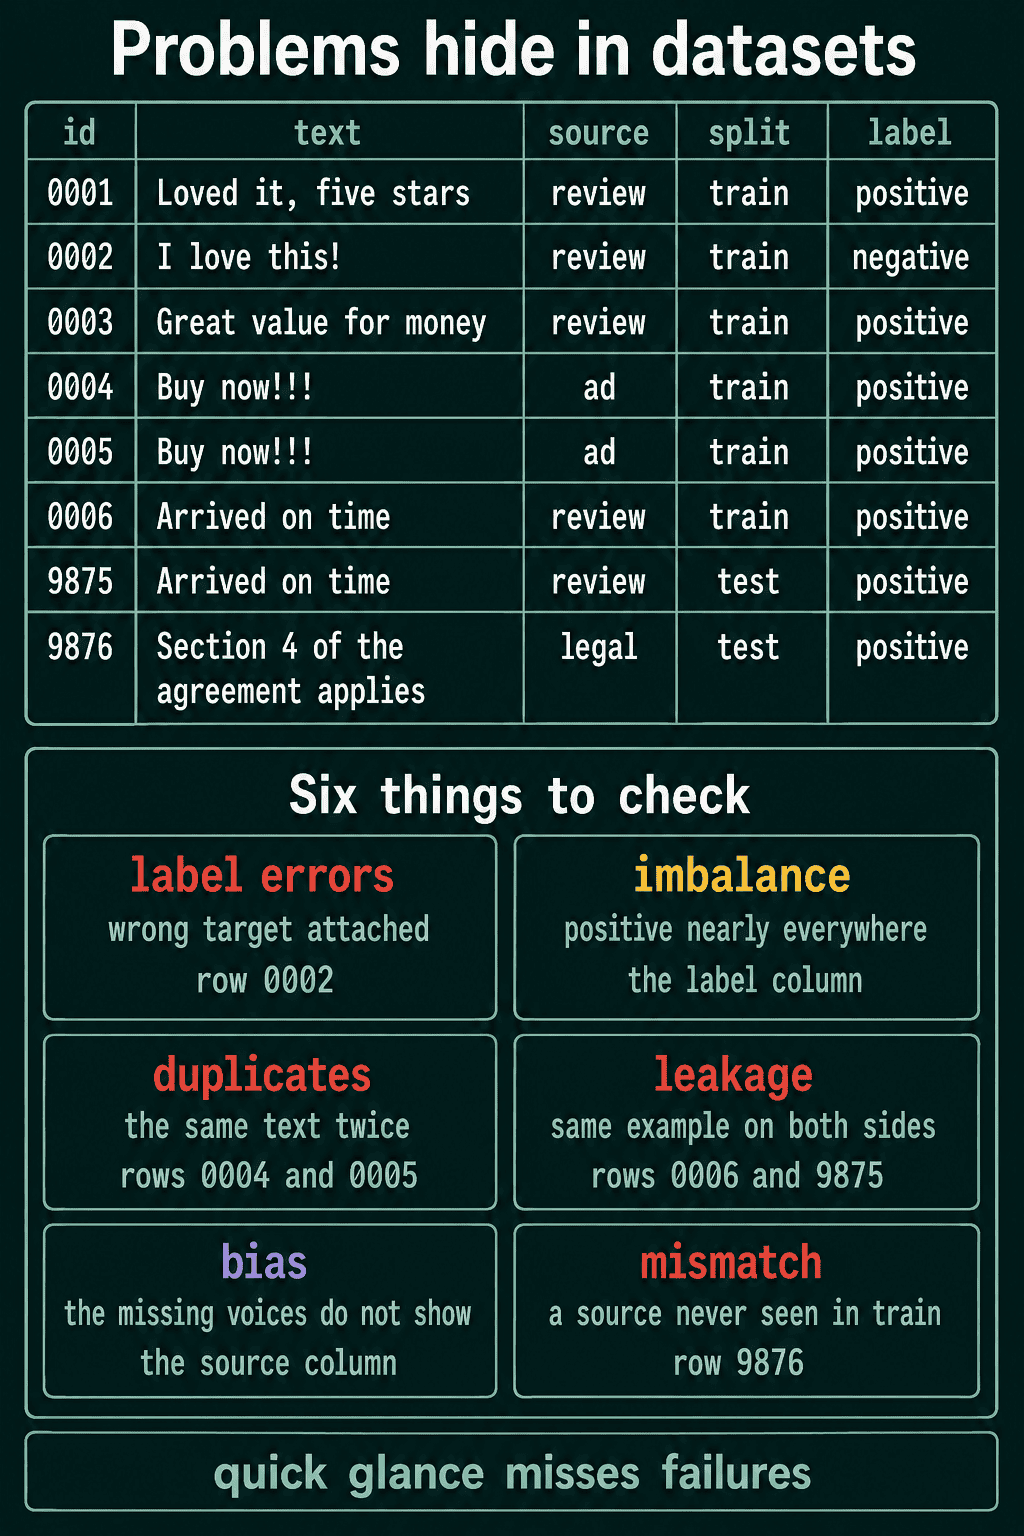
Data quality problems in NLP: duplicates, contamination, bias, and representativeness
The problems to check for in a text dataset before training, how each one changes a model's scores, and short Python checks for duplicates, train/test overlap and test-set size.
 Text as data
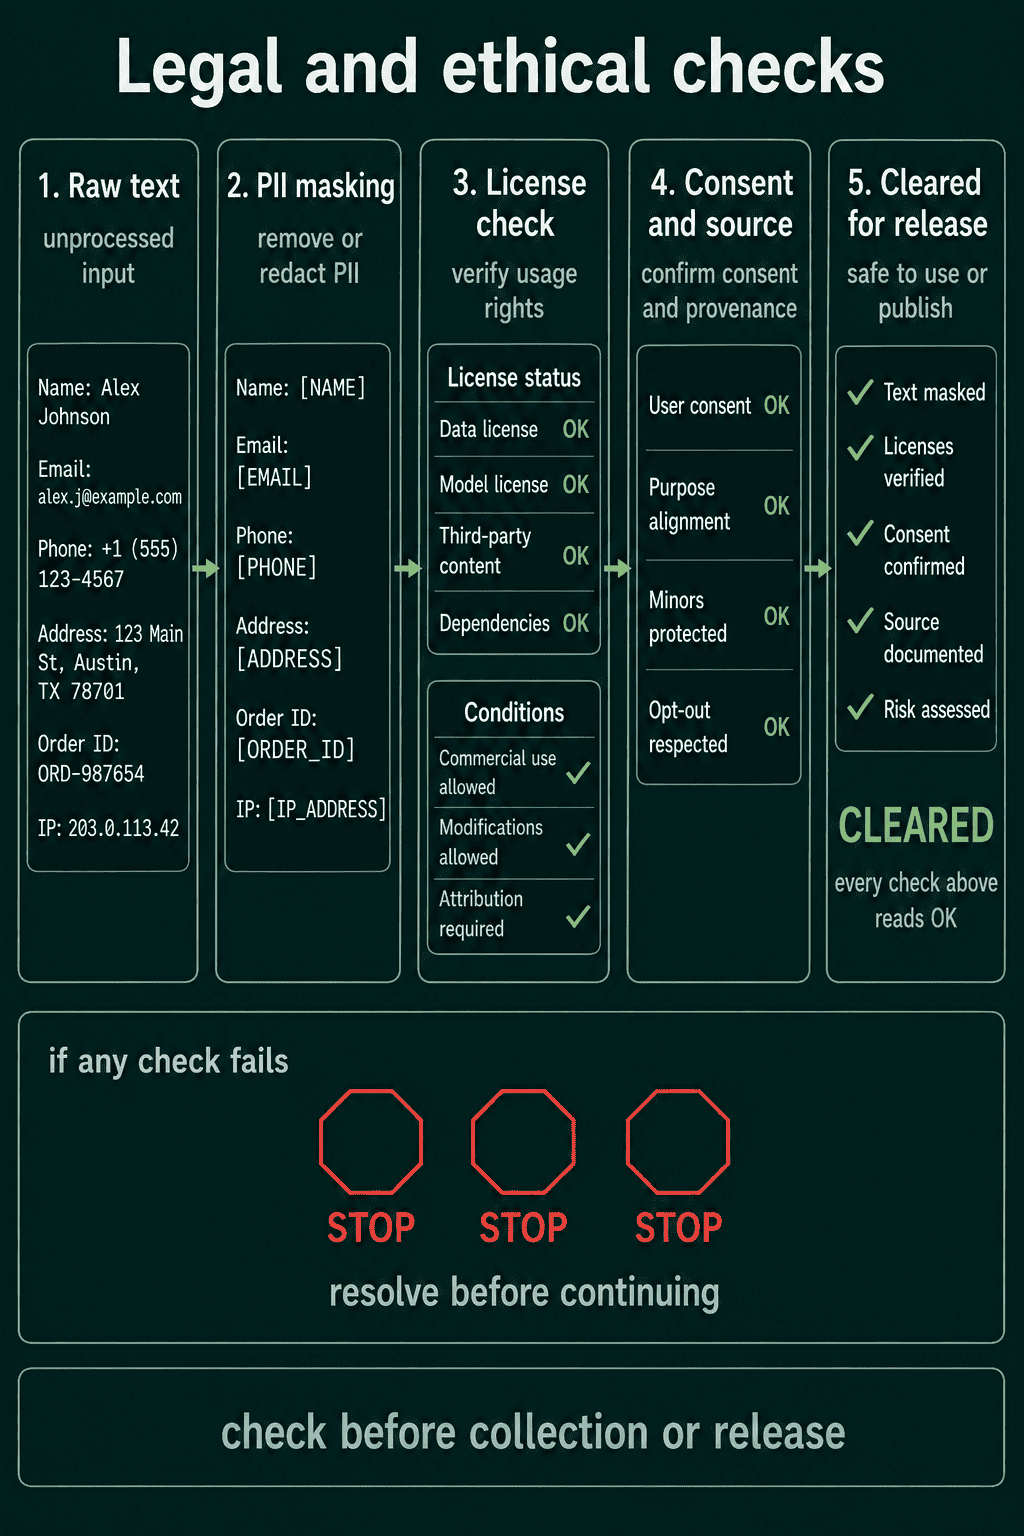
Privacy and licensing: can you train a model on scraped text?
What to check before you collect or publish a text dataset, what a dataset license spells out, and a short Python example that masks emails, phone numbers and IP addresses.
Tokenization
 Tokenization
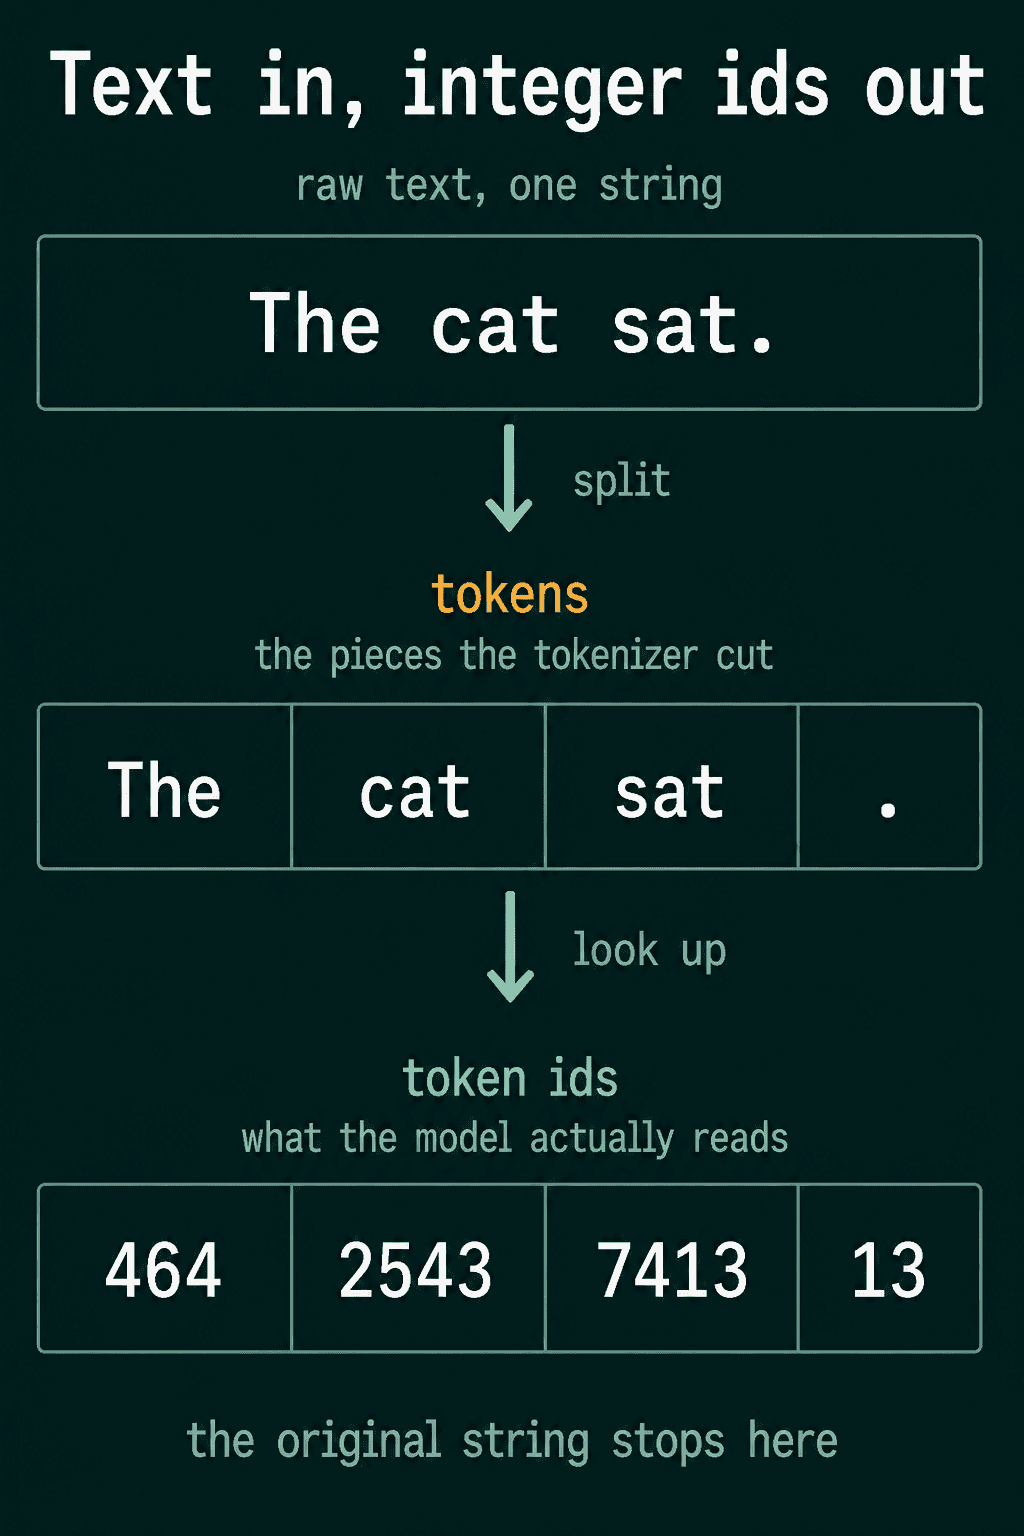
What is tokenization in NLP? Word, character, and subword tokens
Why a language model needs text cut into pieces first, the three questions that decide how big a piece should be, and why most models today use subword tokens instead of whole words or single characters.
 Tokenization
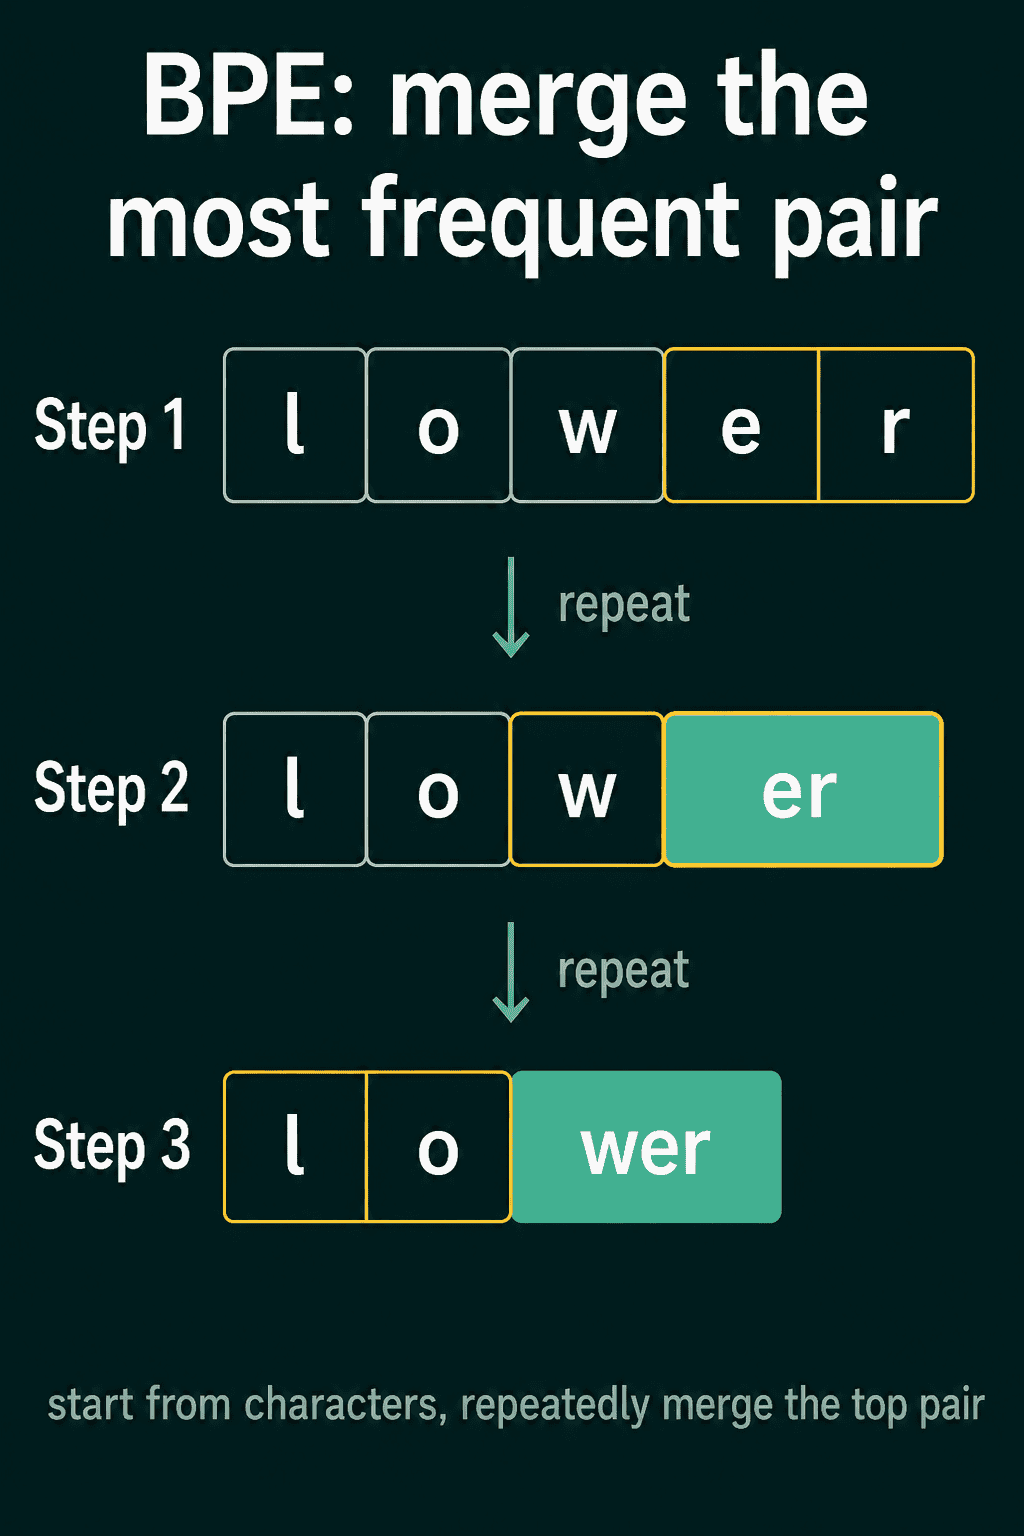
Byte pair encoding (BPE) explained step by step, including byte-level BPE
How BPE builds a subword vocabulary from counts alone, a worked example you can check by hand, the three short Python functions behind it, and why byte-level BPE never needs an unknown token.
 Tokenization
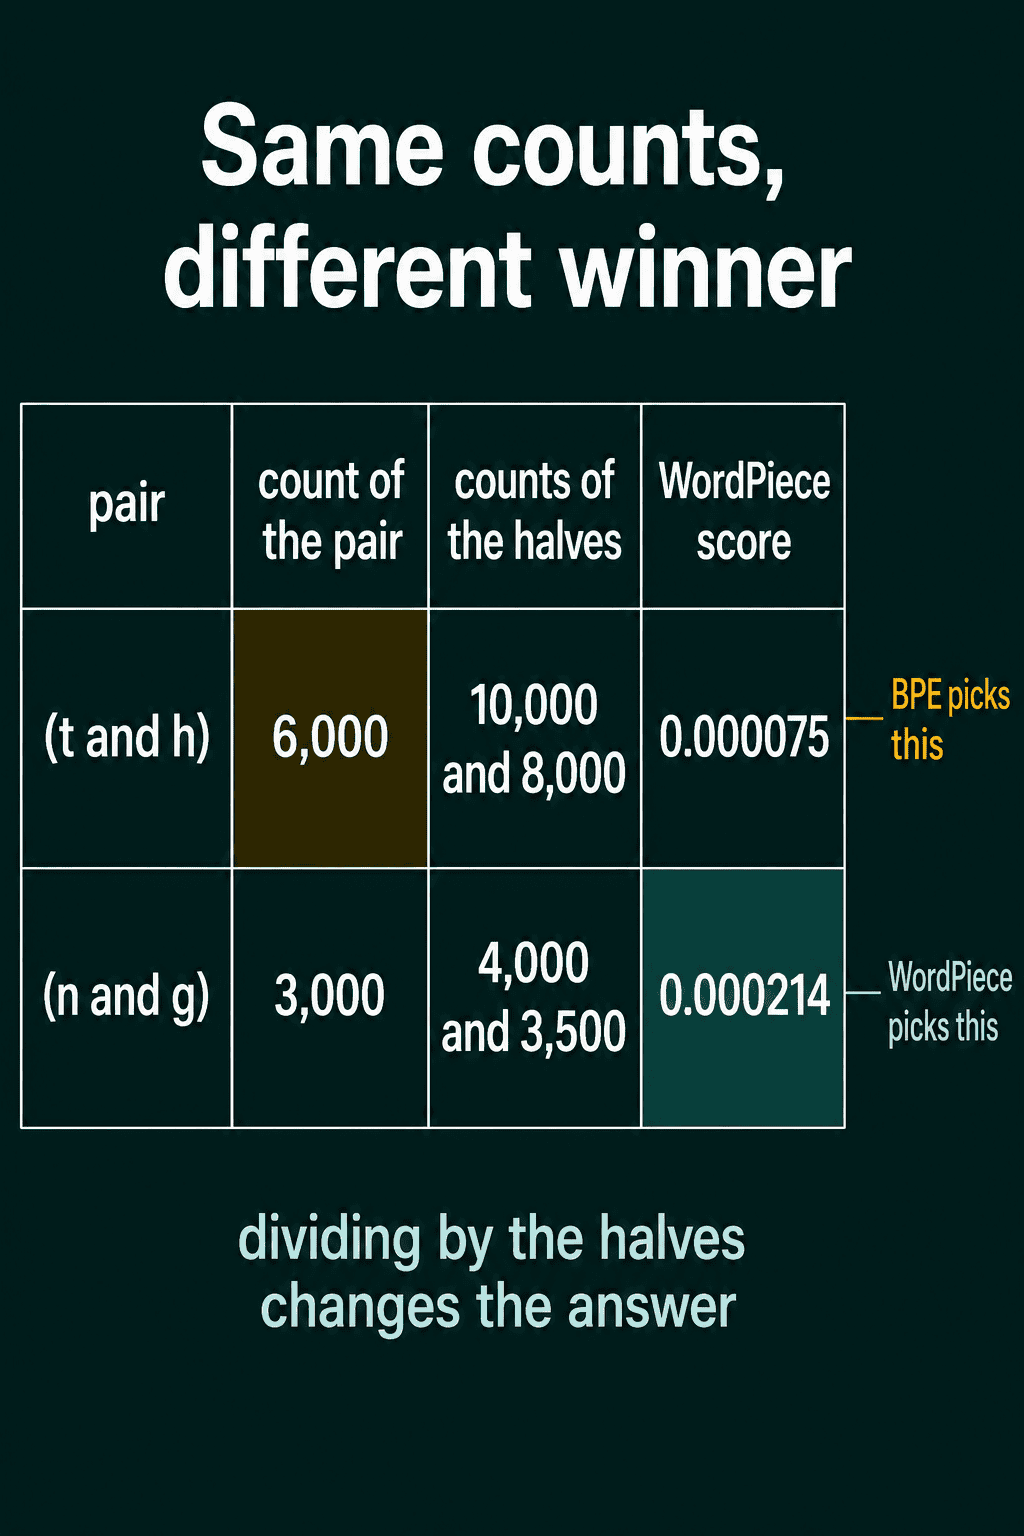
BPE vs WordPiece vs Unigram tokenization
A worked example where BPE and WordPiece merge different pairs, how the ## marker works, and the score Unigram uses to choose between ways of cutting a word.
 Tokenization
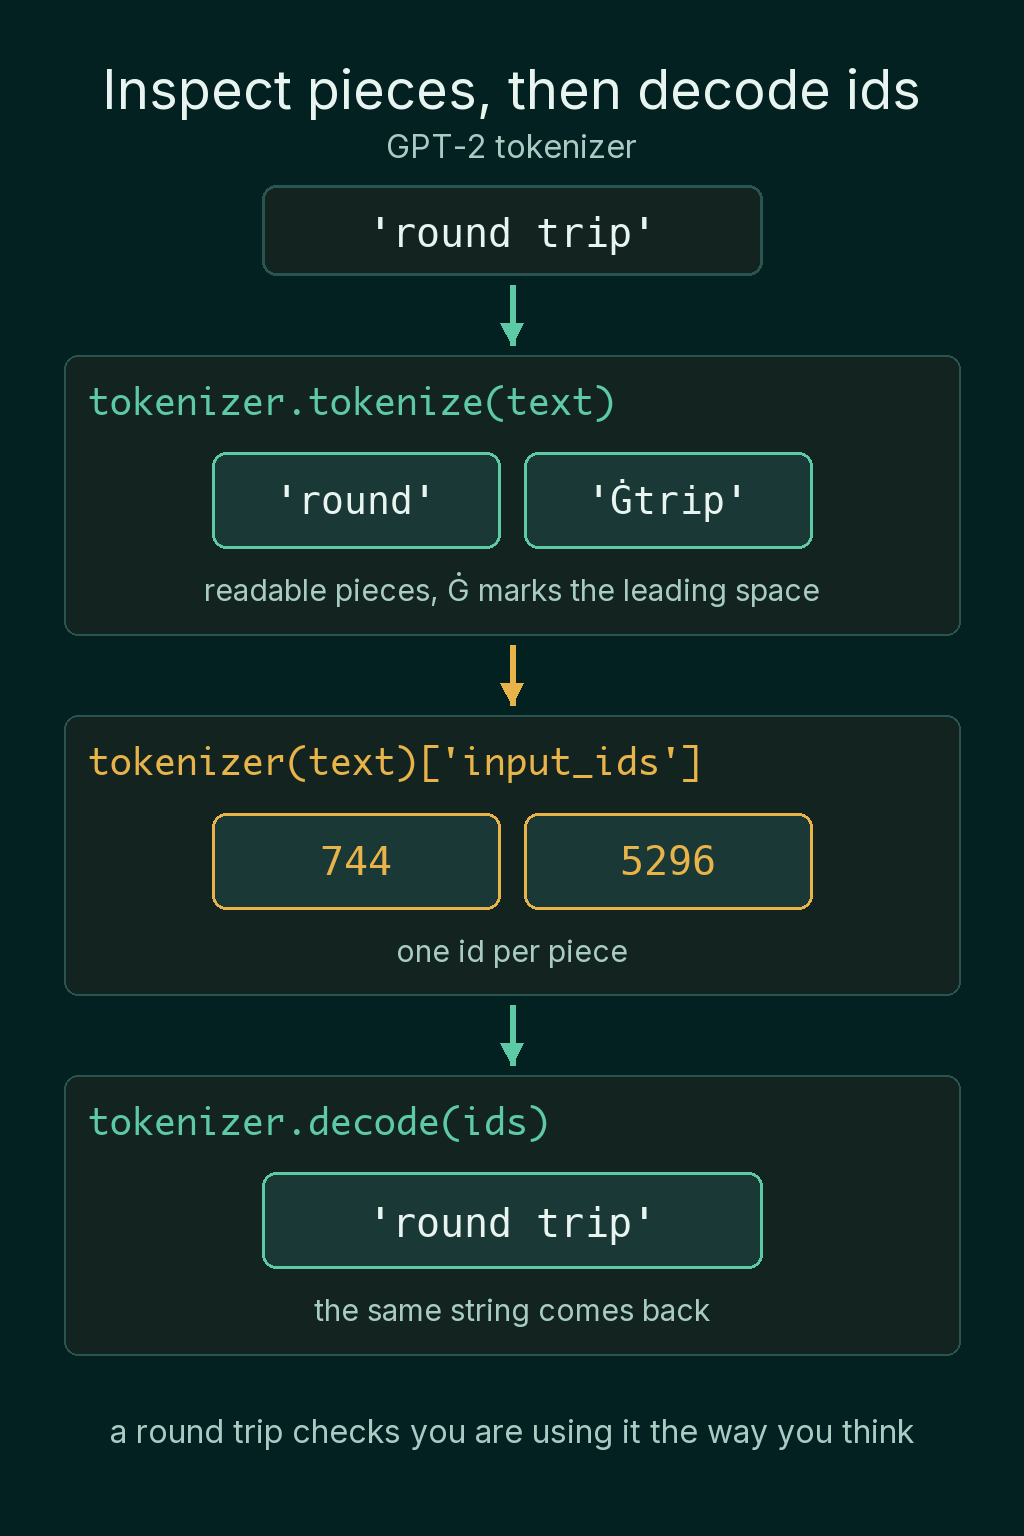
How to use a Hugging Face tokenizer: special tokens, token IDs, padding, and batches
How to load a pretrained tokenizer and read what it returns, the four stages a string passes through, and how to batch sentences of different lengths with padding and truncation.
 Tokenization
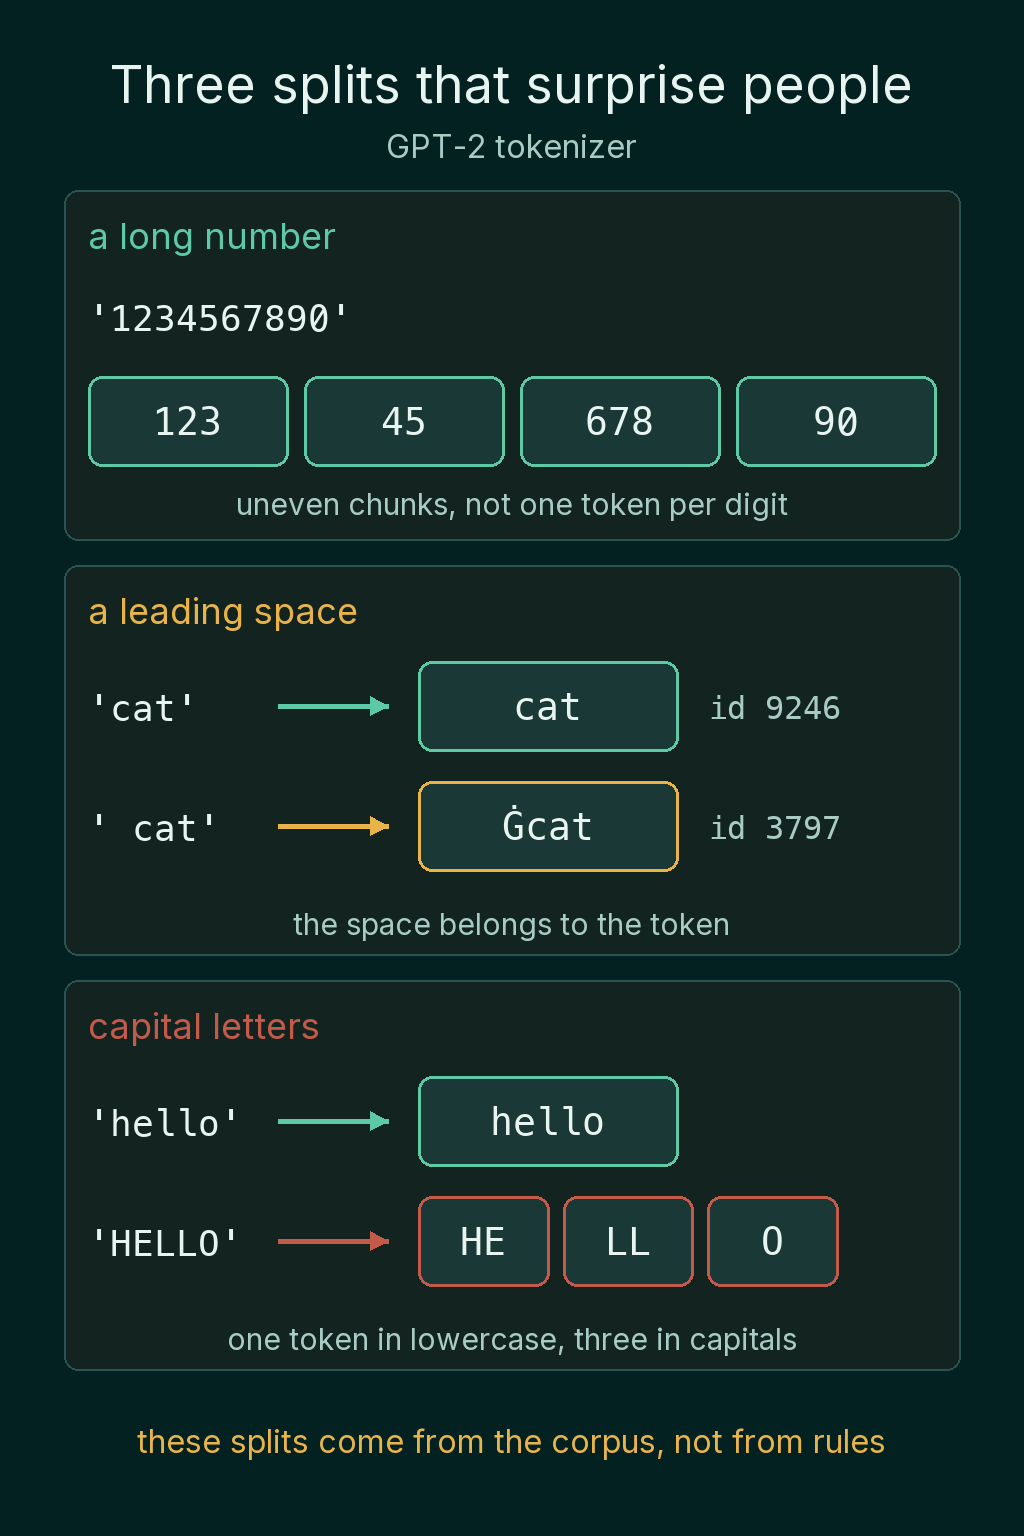
Why LLMs miscount letters: tokenization quirks and non-English text
What GPT-2's tokenizer does to a word, a number and an emoji, how many tokens one sentence takes in four languages, and why some tokens make a model behave strangely.
Word representations
 Word representations
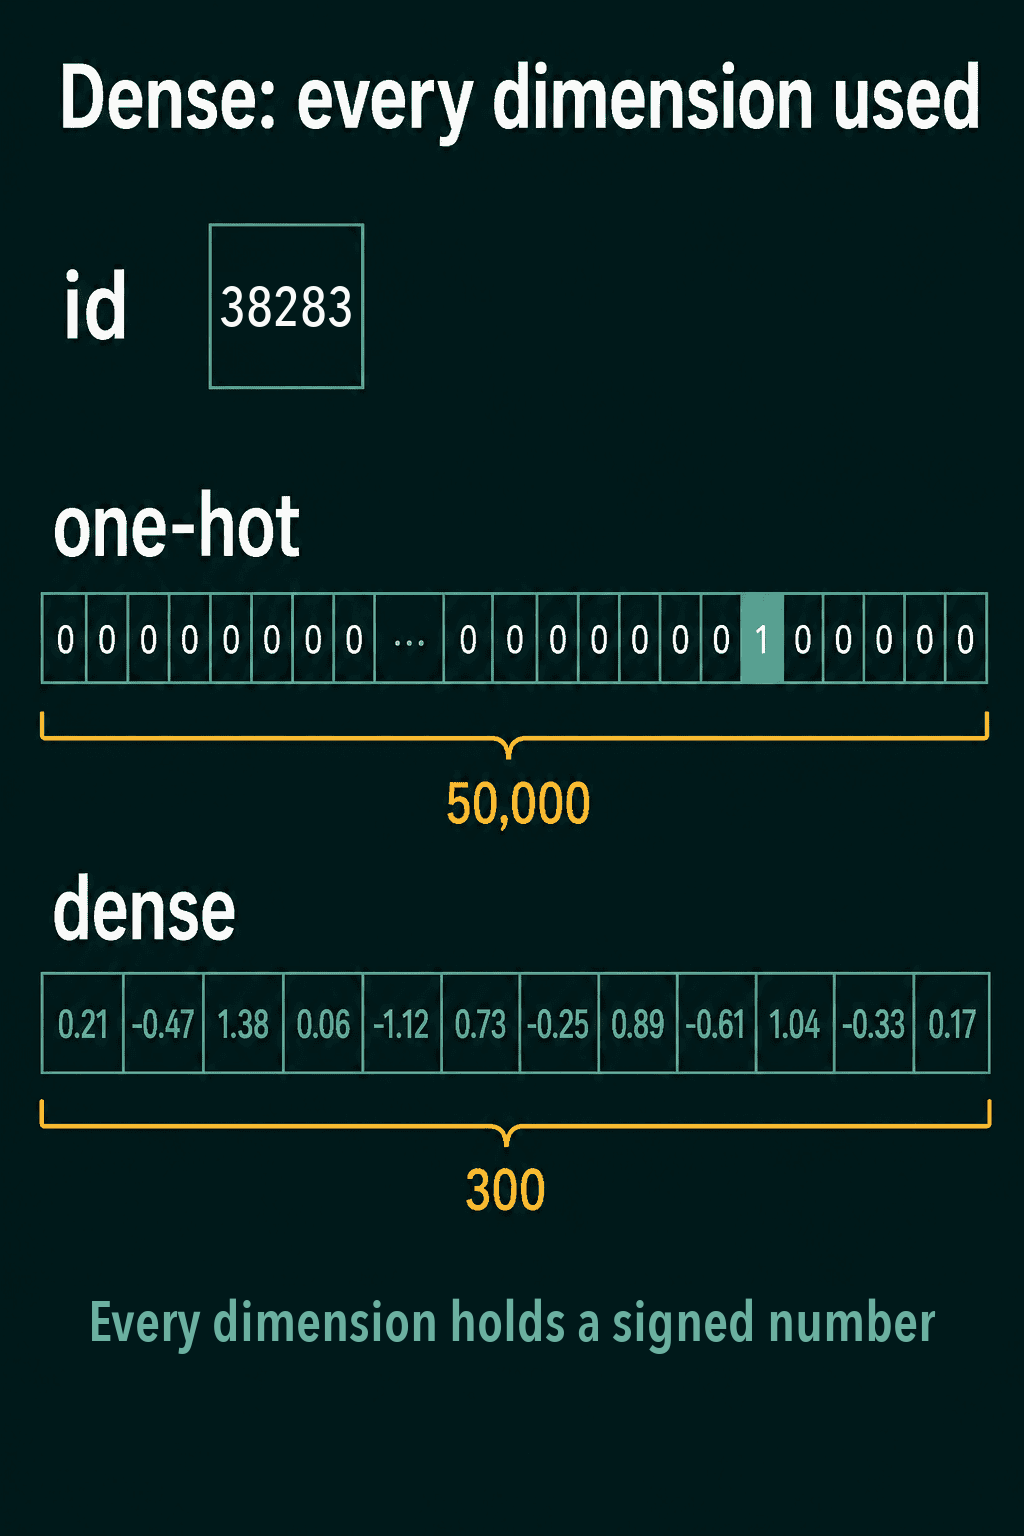
How to turn words into numbers: integer encoding, one-hot, and dense vectors
How to measure whether two word vectors are close with distance and cosine similarity, why token ids and one-hot vectors cannot show which words are related, and what a dense vector changes.
 Word representations
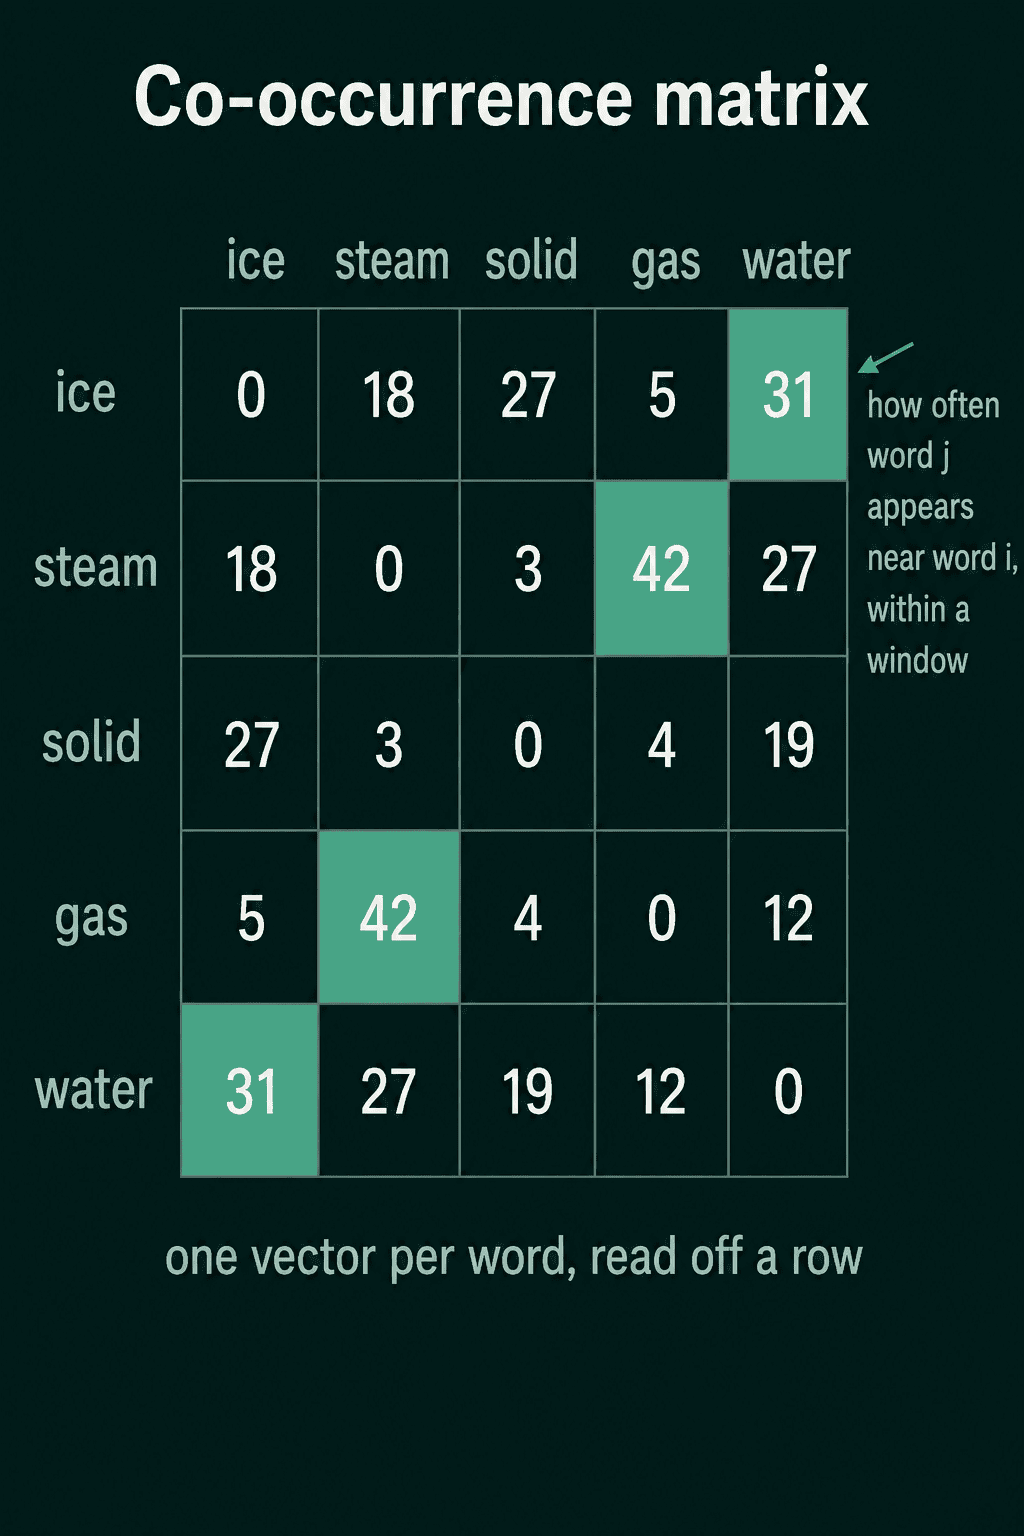
Bag of words, co-occurrence matrices, and PMI: count-based word vectors
How counting the words around each word turns raw text into vectors, with PyTorch code for a bag-of-words vector, a co-occurrence matrix and PPMI, and what each of them loses.
 Word representations
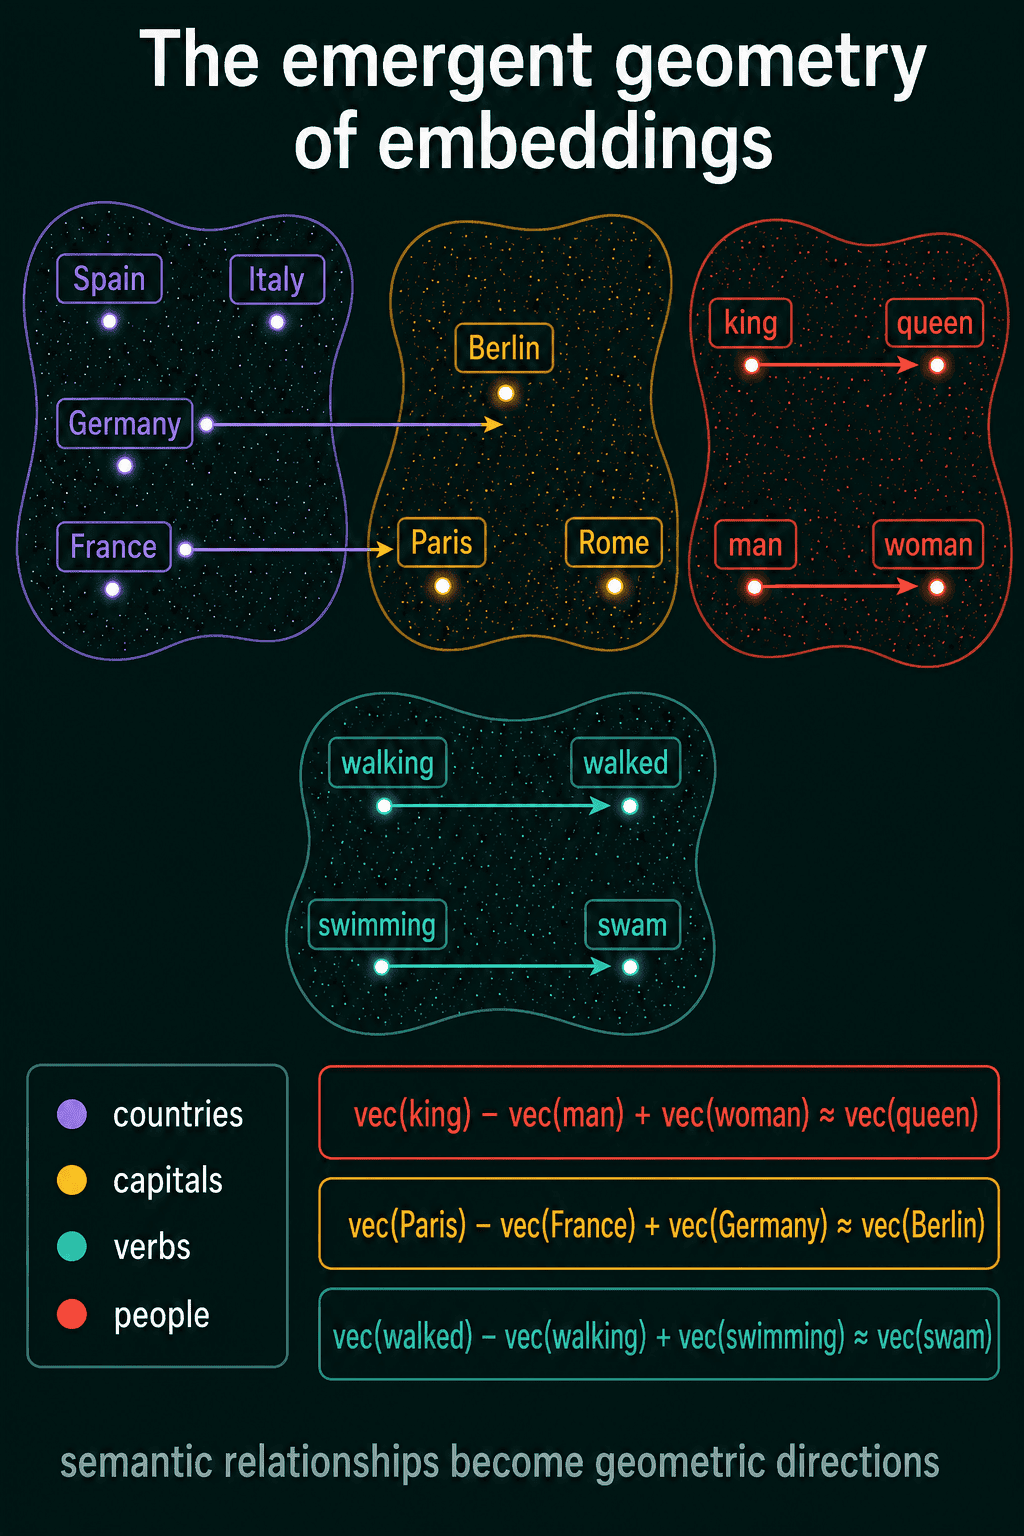
What are word embeddings?
How an embedding table turns a token id into a vector in PyTorch, why training can move those vectors, and how relationships like king to queen show up as directions, with the bug that breaks analogy search.
Word representations
Bag of words, co-occurrence matrices, and PMI: count-based word vectors
How counting the words around each word turns raw text into vectors, with PyTorch code for a bag-of-words vector, a co-occurrence matrix and PPMI, and what each of them loses.
Word representations
How to turn words into numbers: integer encoding, one-hot, and dense vectors
How to measure whether two word vectors are close with distance and cosine similarity, why token ids and one-hot vectors cannot show which words are related, and what a dense vector changes.
Word representations
What are word embeddings?
How an embedding table turns a token id into a vector in PyTorch, why training can move those vectors, and how relationships like king to queen show up as directions, with the bug that breaks analogy search.
Tokenization
BPE vs WordPiece vs Unigram tokenization
A worked example where BPE and WordPiece merge different pairs, how the ## marker works, and the score Unigram uses to choose between ways of cutting a word.
Tokenization
How to use a Hugging Face tokenizer: special tokens, token IDs, padding, and batches
How to load a pretrained tokenizer and read what it returns, the four stages a string passes through, and how to batch sentences of different lengths with padding and truncation.
Tokenization
Why LLMs miscount letters: tokenization quirks and non-English text
What GPT-2's tokenizer does to a word, a number and an emoji, how many tokens one sentence takes in four languages, and why some tokens make a model behave strangely.
Tokenization
Byte pair encoding (BPE) explained step by step, including byte-level BPE
How BPE builds a subword vocabulary from counts alone, a worked example you can check by hand, the three short Python functions behind it, and why byte-level BPE never needs an unknown token.
Text as data
Privacy and licensing: can you train a model on scraped text?
What to check before you collect or publish a text dataset, what a dataset license spells out, and a short Python example that masks emails, phone numbers and IP addresses.
Tokenization
What is tokenization in NLP? Word, character, and subword tokens
Why a language model needs text cut into pieces first, the three questions that decide how big a piece should be, and why most models today use subword tokens instead of whole words or single characters.
Text as data
How to handle class imbalance in text classification
Why a spam filter can score 98% accuracy while catching no spam, which numbers to report instead, and how reweighting, oversampling and undersampling work in PyTorch, with what each one costs.
Text as data
Data quality problems in NLP: duplicates, contamination, bias, and representativeness
The problems to check for in a text dataset before training, how each one changes a model's scores, and short Python checks for duplicates, train/test overlap and test-set size.
Text as data
Text preprocessing in NLP: normalization, stemming vs lemmatization, and stopwords
What each classic cleanup step does to a sentence, with runnable NLTK code, where each one erases something a model could use, and how much of it to apply for a count-based model versus a transformer.
Text as data
Data annotation for NLP: crowdsourcing vs experts, and inter-annotator agreement
How to design labels people can apply consistently, when to pay a crowd and when to hire experts, and how to compute Cohen's kappa to check whether your labels can be trusted.
Text as data
How to build your own NLP dataset: selecting data, extracting text, documenting it
How to choose the text for a custom dataset and pull clean text out of web pages, PDFs and scans, plus what to write down so the next person can trust it.
Text as data
Where to find NLP datasets: Hugging Face Hub, Kaggle, and more
Which places to search for a text dataset, how to load one in Python, and what to check before you train anything on it.
What NLP is
A short history of NLP: from ELIZA to deep learning
The four eras NLP went through on its way to today's large models, why each shift happened, and what the 1960s chatbot ELIZA shows about sounding smart without understanding anything.
Text as data
Unicode and UTF-8 explained: how computers store text
How a character becomes a code point and then bytes, why the same word can take a different number of bytes in different scripts, and how to fix text that compares wrong or shows up garbled.
Text as data
Why text is hard data for machine learning
How raw text differs from tables and images, and the three decisions an NLP system has to make before a model can learn anything from it.
What NLP is
What is NLP? Natural language processing explained
The main NLP tasks from sentiment analysis to language modeling, the kinds of ambiguity that make human language hard for a computer, and why modern NLP learns from data instead of following hand-written rules.
What NLP is
How to learn NLP in 2026: a complete roadmap from text to LLMs
What to learn for natural language processing and in what order, from tokenization and word embeddings to transformers, LLMs and post-training, so you can see what is ahead and check off what you already know.
No posts match your search.