ML Foundations
How models learn, neural networks, optimization, generalization, and evaluation. Posts are listed in the order the ideas build on each other.
How a model learns
 How a model learns
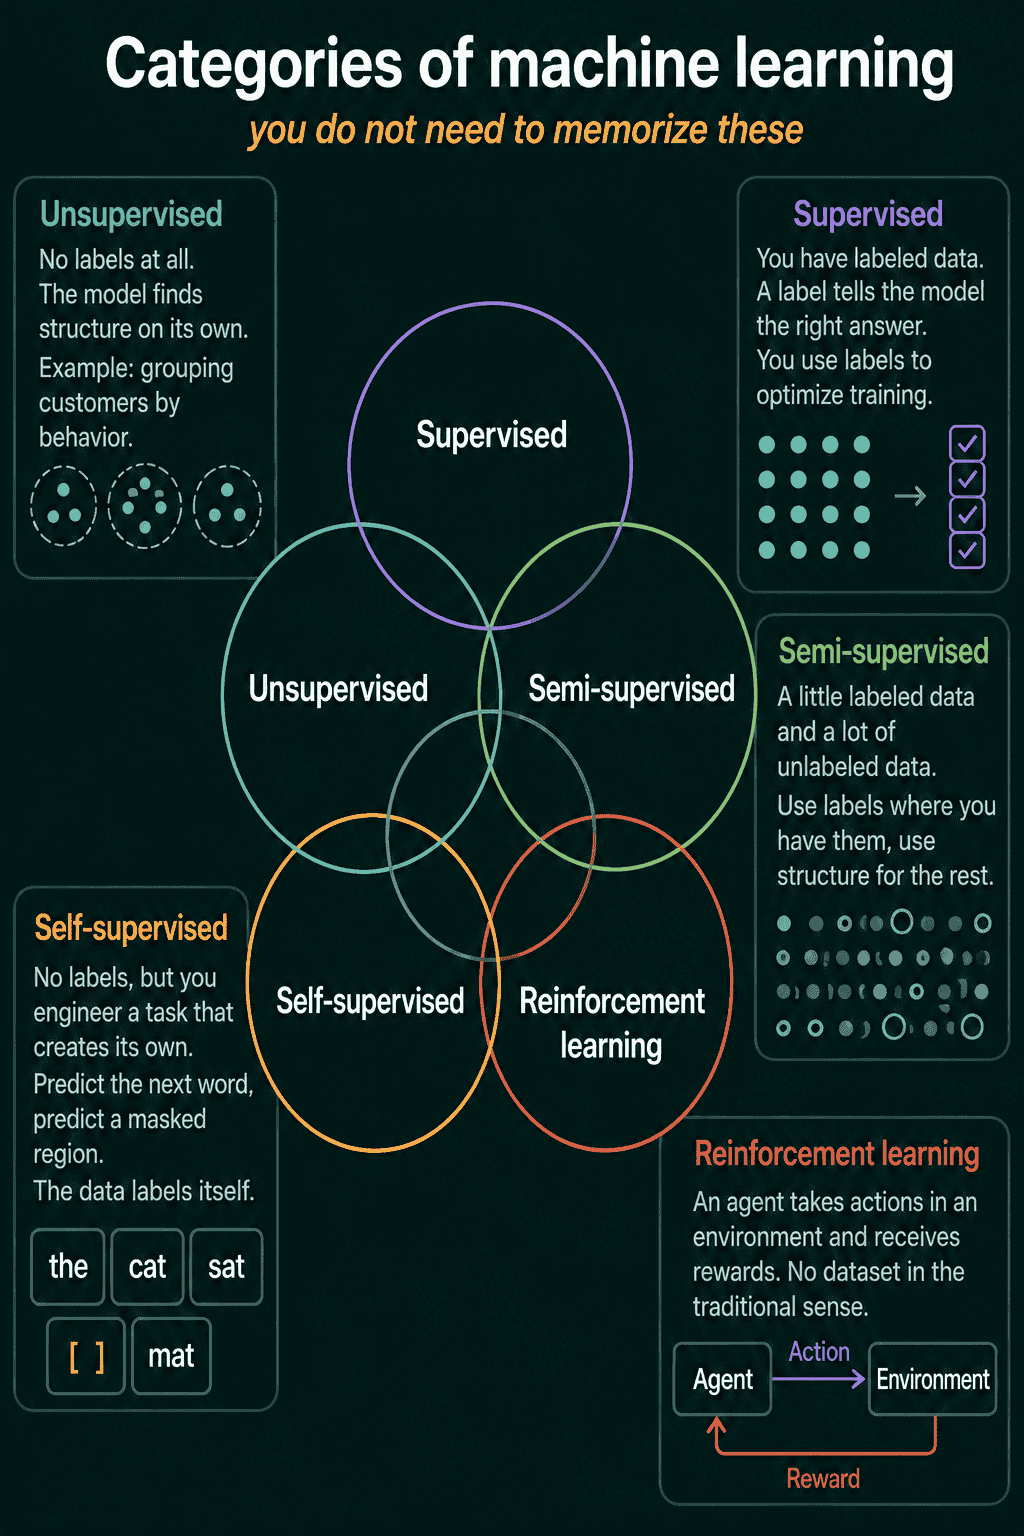
What is machine learning? The 5 types of learning explained
Machine learning is a way to build software that learns its rules from examples instead of having them written by hand. This post explains how that works and why it can work on data the model has never seen, then walks through the five types of learning (supervised, unsupervised, semi-supervised, self-supervised, and reinforcement learning) with an example of each and how to pick between them.
 How a model learns
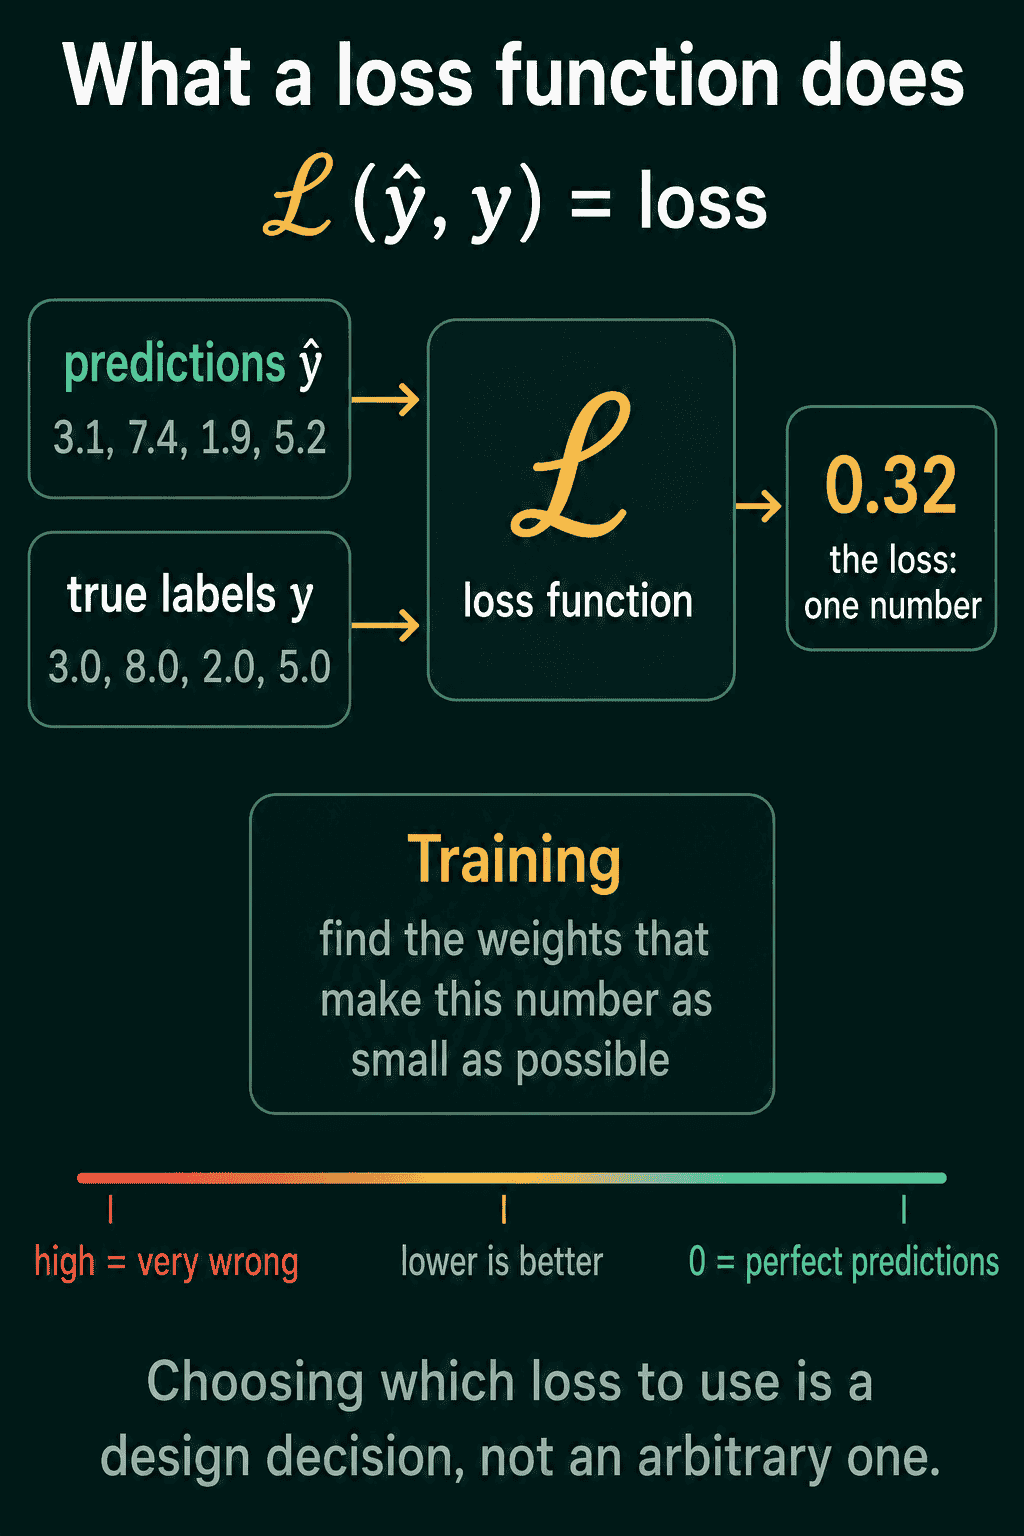
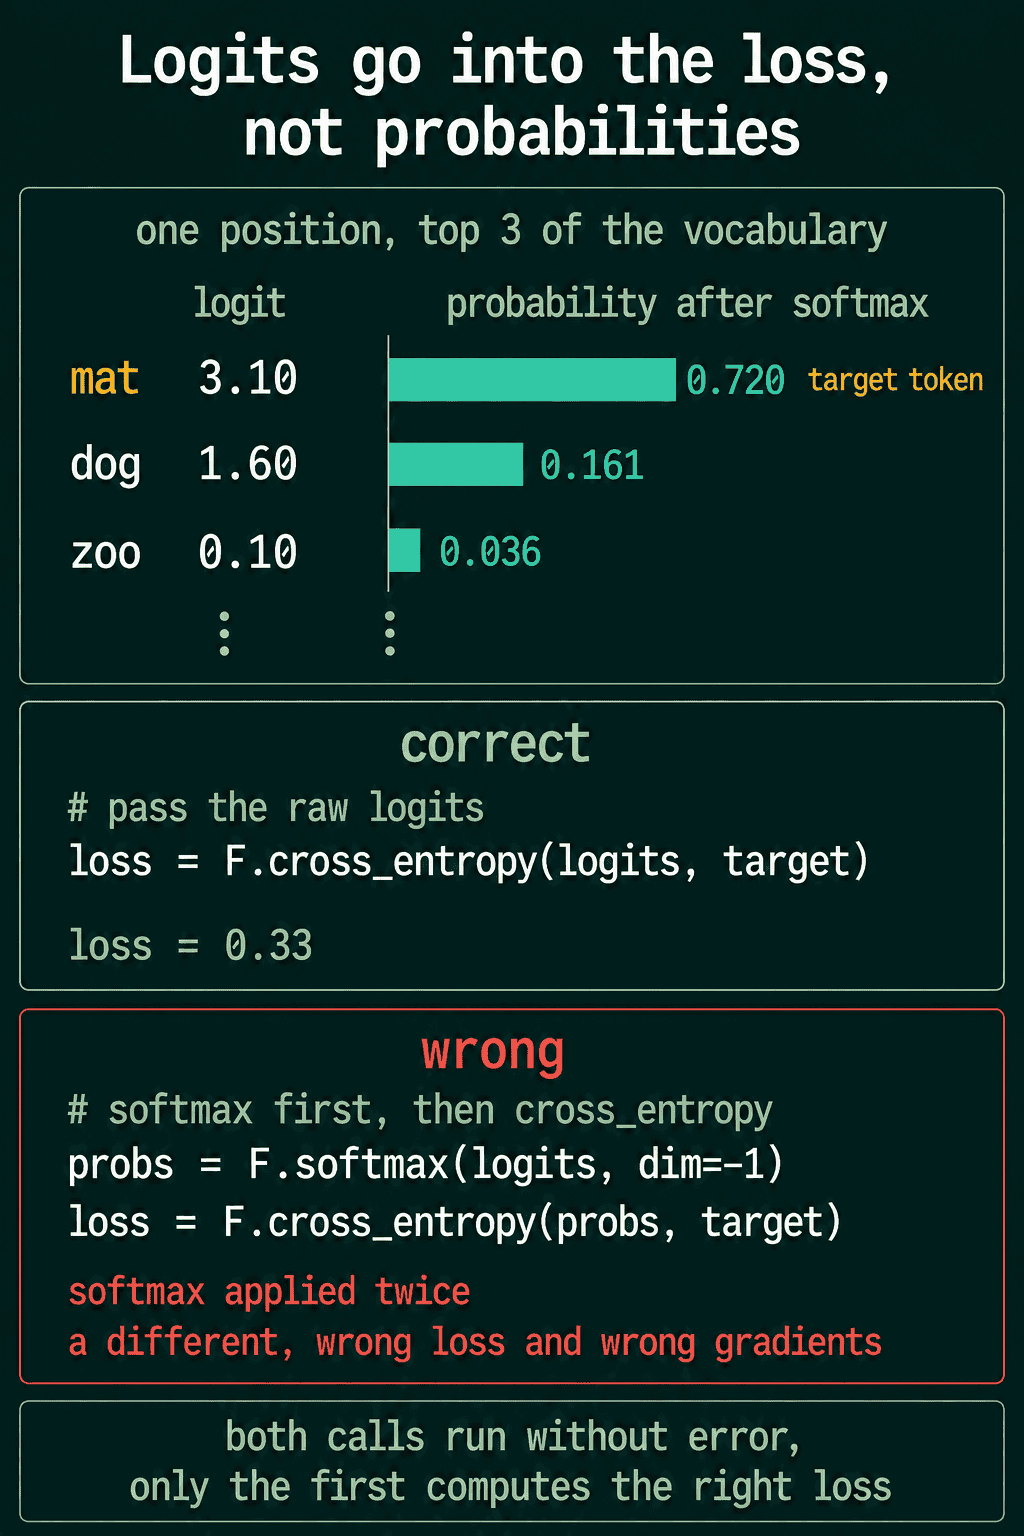
What is a loss function? MSE, cross-entropy, and when to use which
A loss function turns a model's predictions into one number that says how wrong they are, and training is the process of pushing that number down. This post explains why models need one, which loss to use for regression, binary, multi-class, and multi-label problems (and for a few other tasks), and how to use the loss on a proper validation split to evaluate a model.
 How a model learns
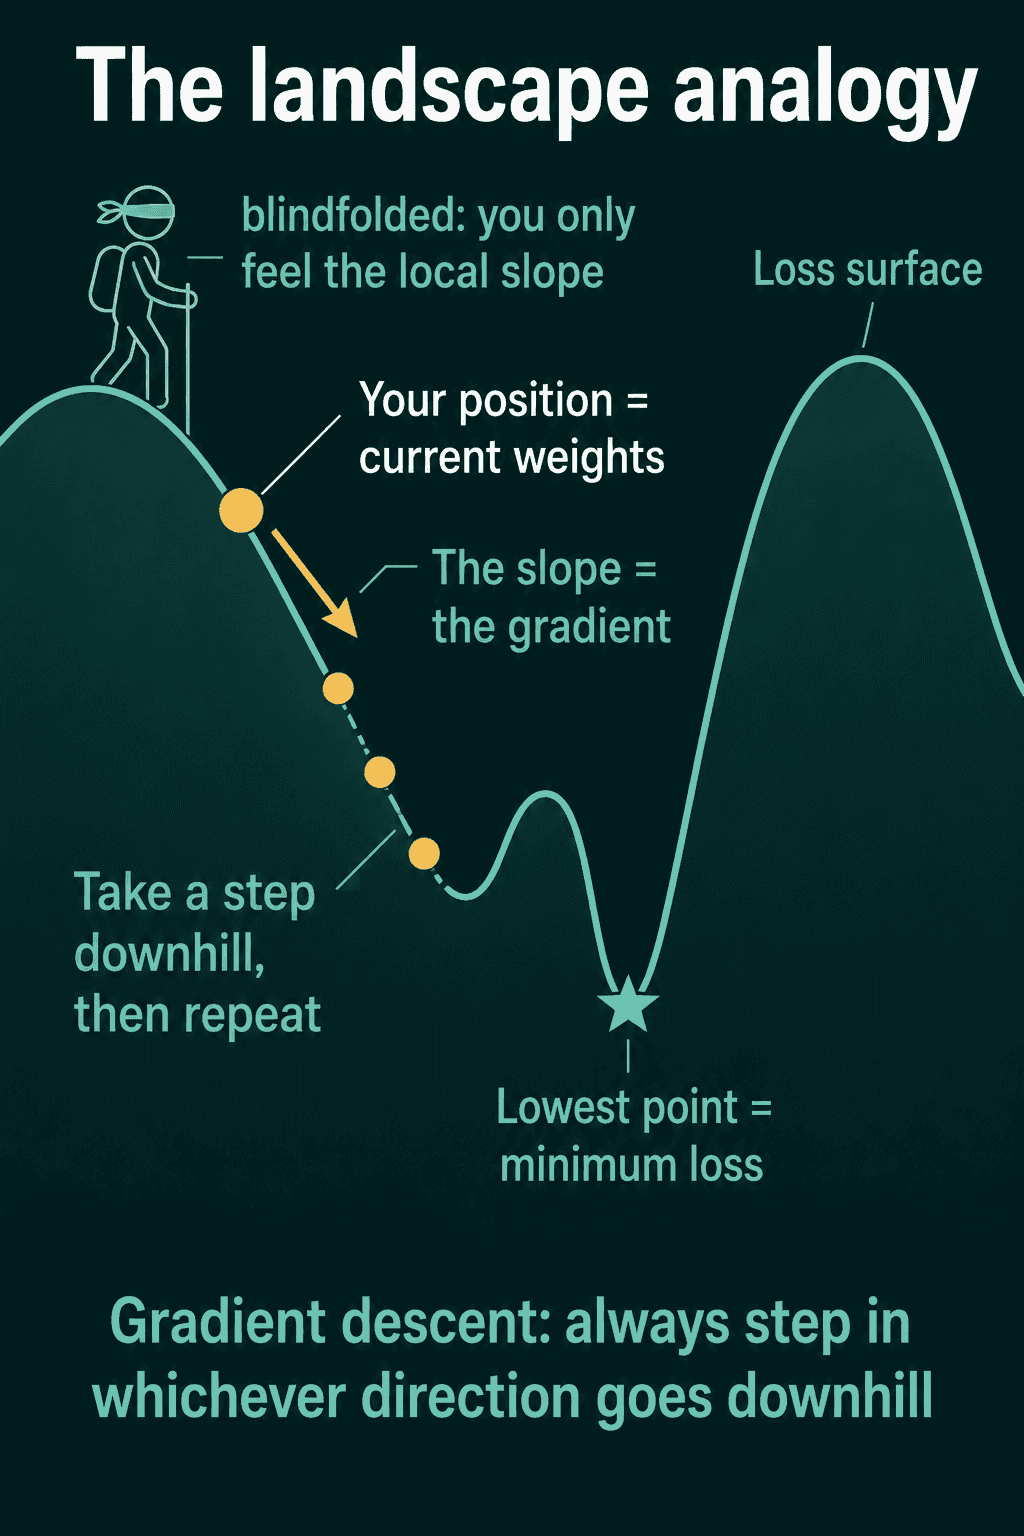
What is gradient descent? Explained step by step
Gradient descent is the procedure that trains almost every machine learning model. This post explains what it does, why the update has a minus sign, how the learning rate changes everything, and what the three lines of PyTorch that implement it are doing.
 How a model learns
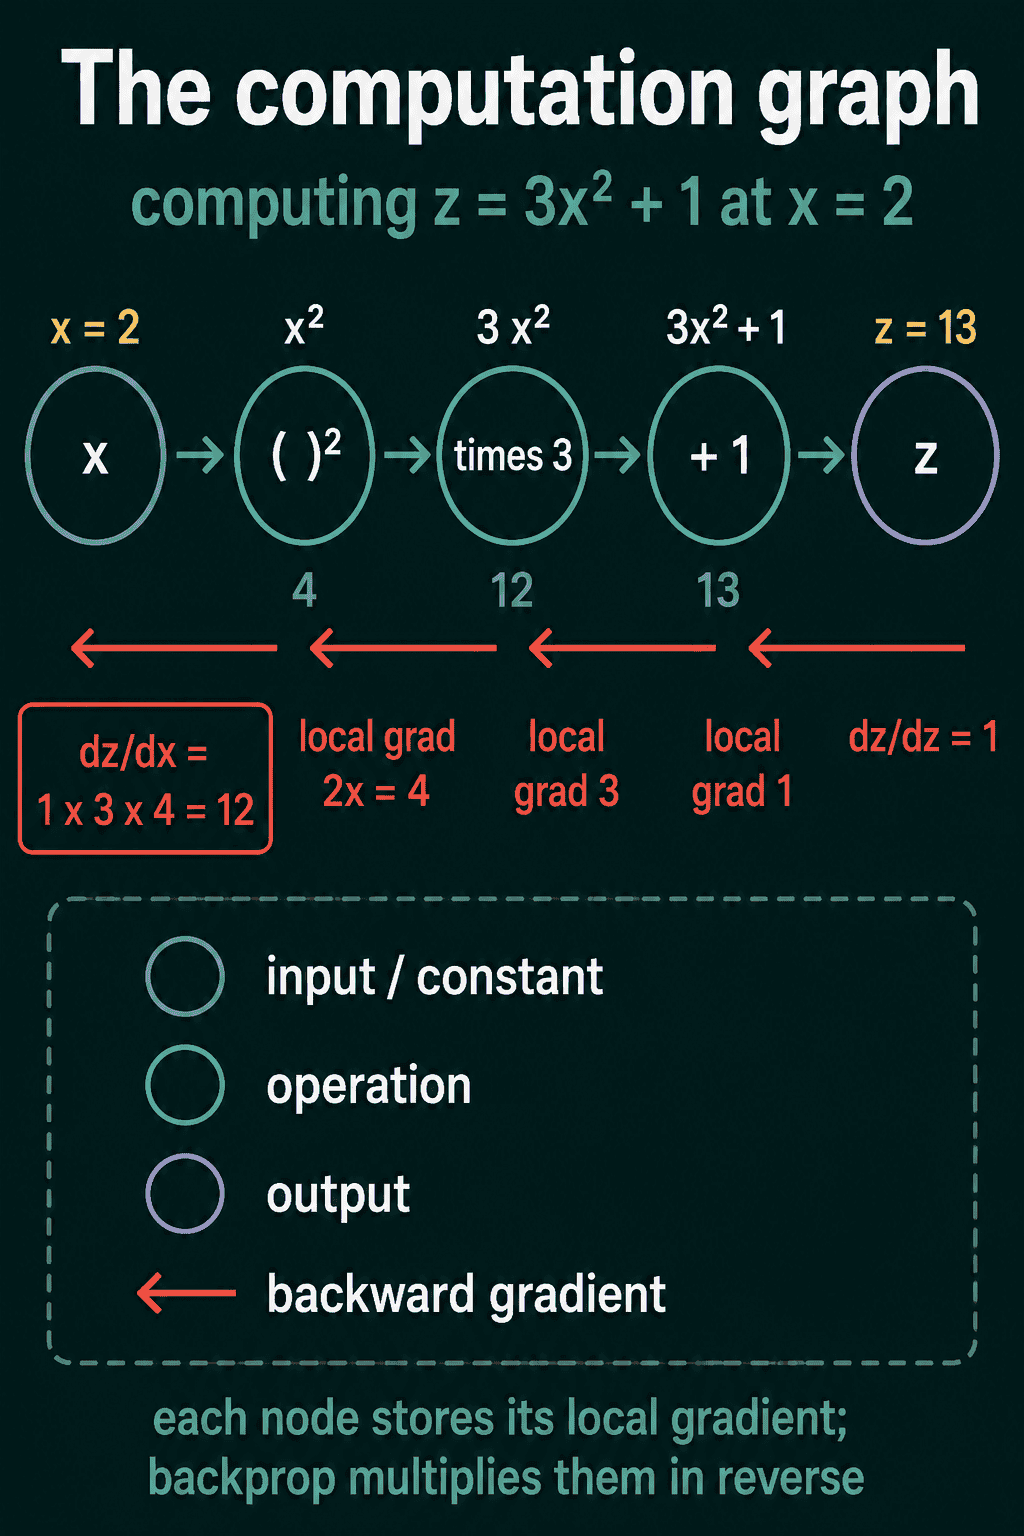
What is backpropagation? Explained with a tiny network
Backpropagation is how a neural network works out which way to change each of its weights to reduce its error. This post computes it by hand on a network with two weights, shows why it runs backward, and checks the numbers against PyTorch.
Neural networks
 Neural networks
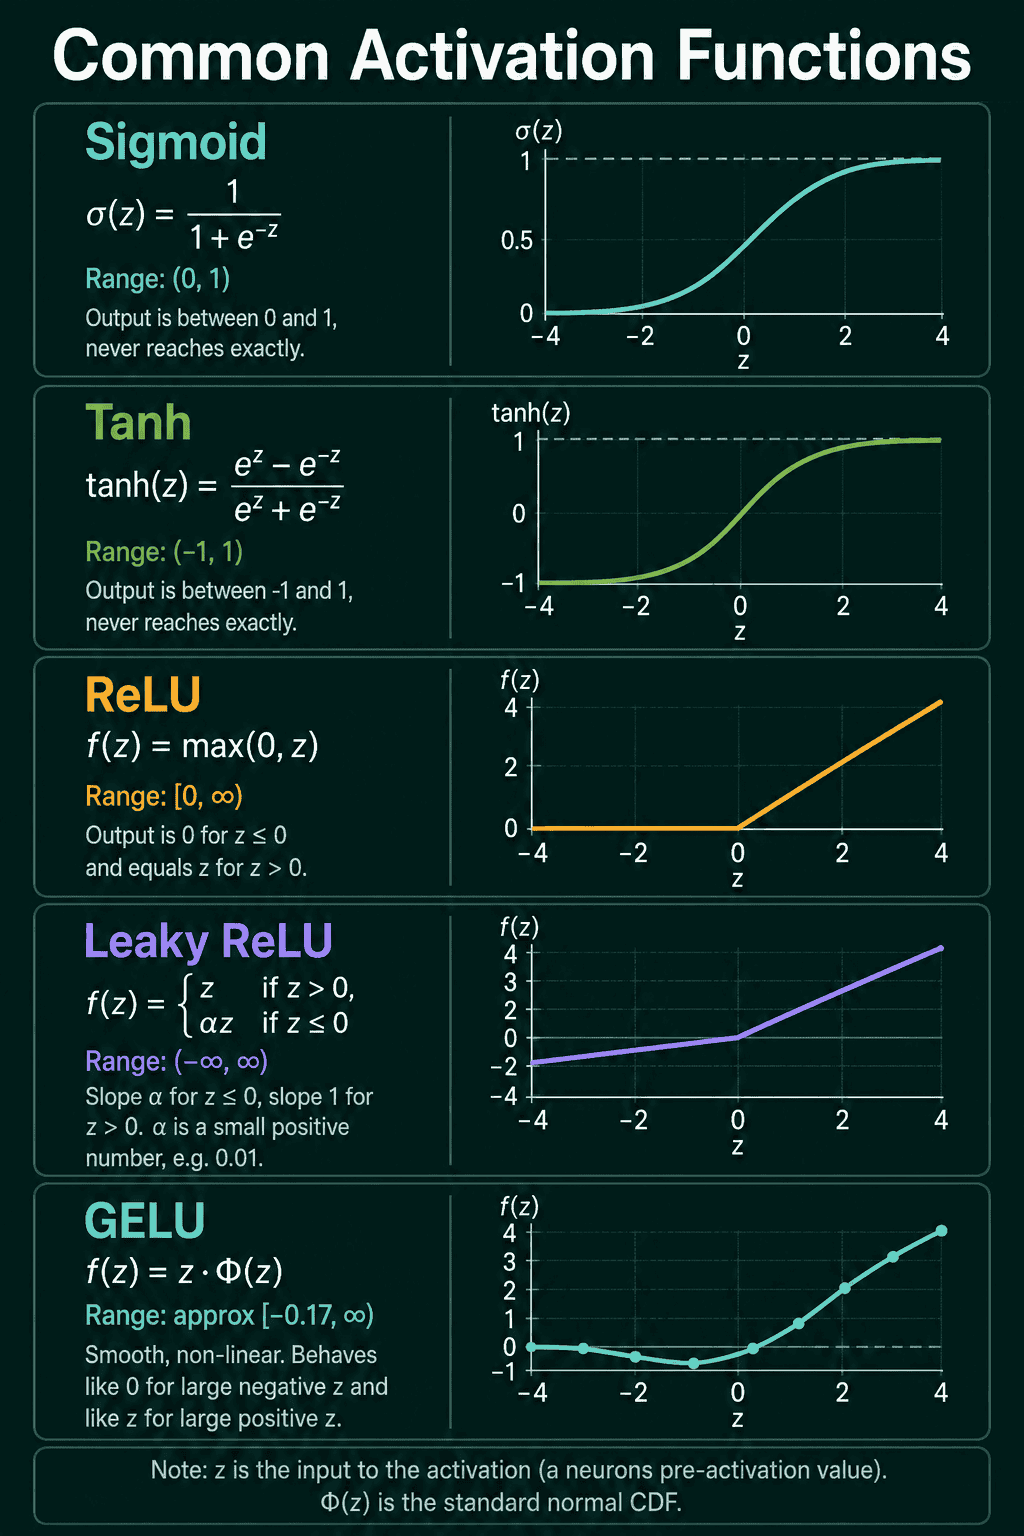
Activation functions roadmap: step, sigmoid, tanh, ReLU, Leaky ReLU, GELU
Optimization
 Optimization
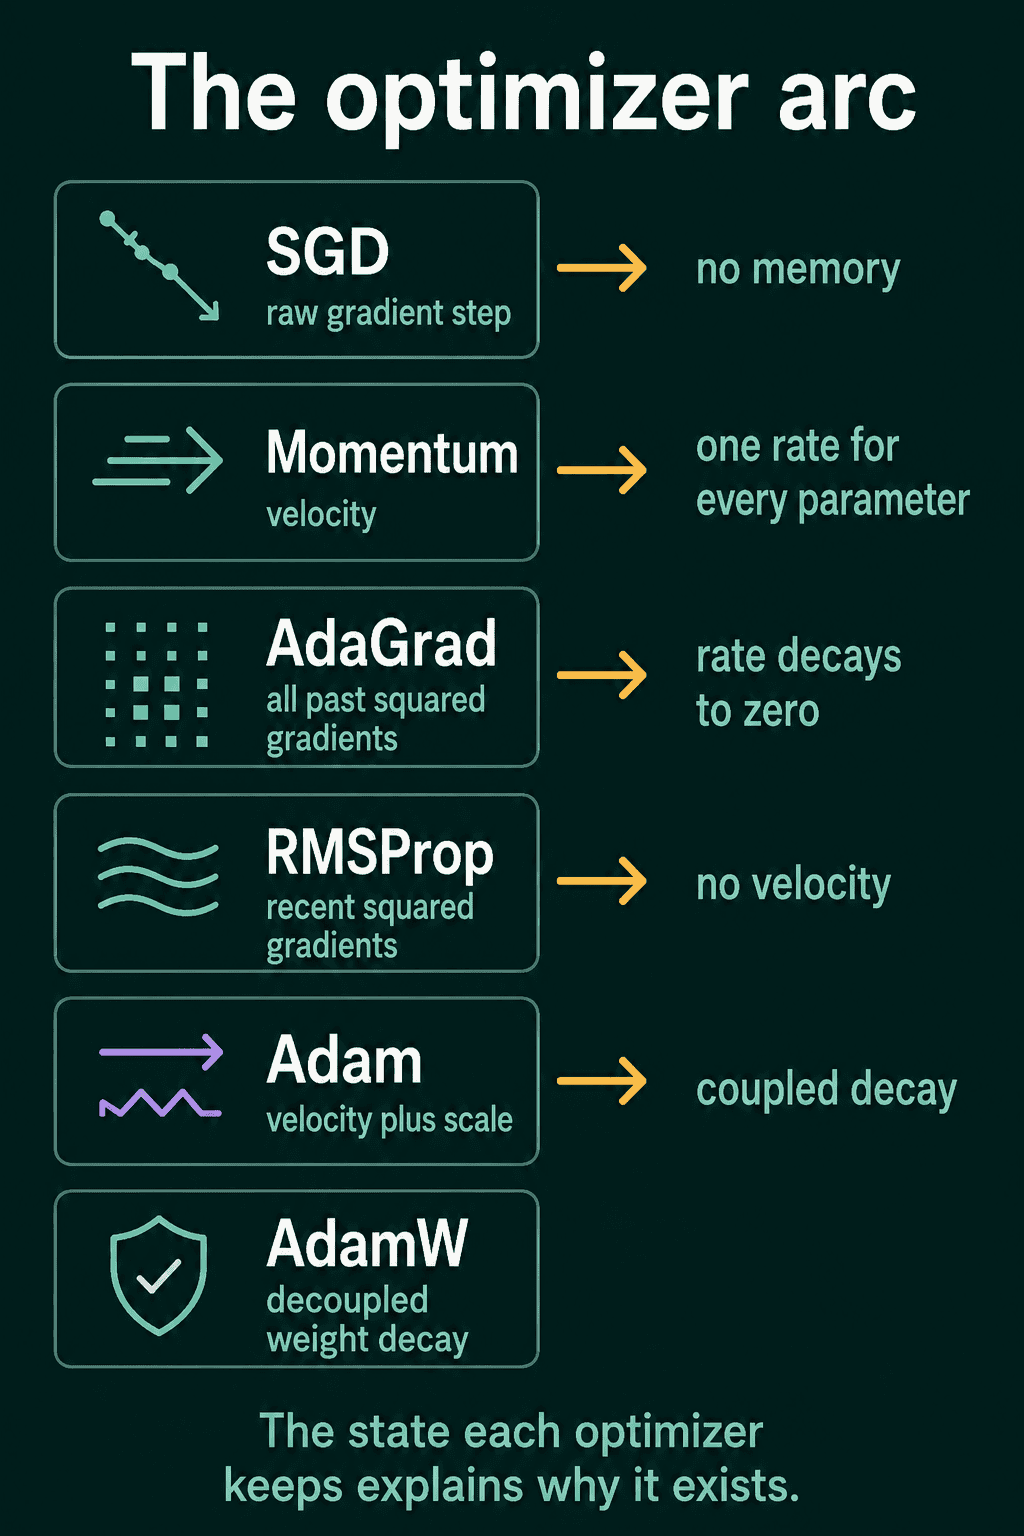
Machine learning optimizers explained: SGD, momentum, RMSProp, Adam, AdamW
An optimizer is the rule that turns gradients into parameter updates. This post explains the five optimizers most models train with, in the order each one was invented to fix the last, and which one to pick.
 Optimization
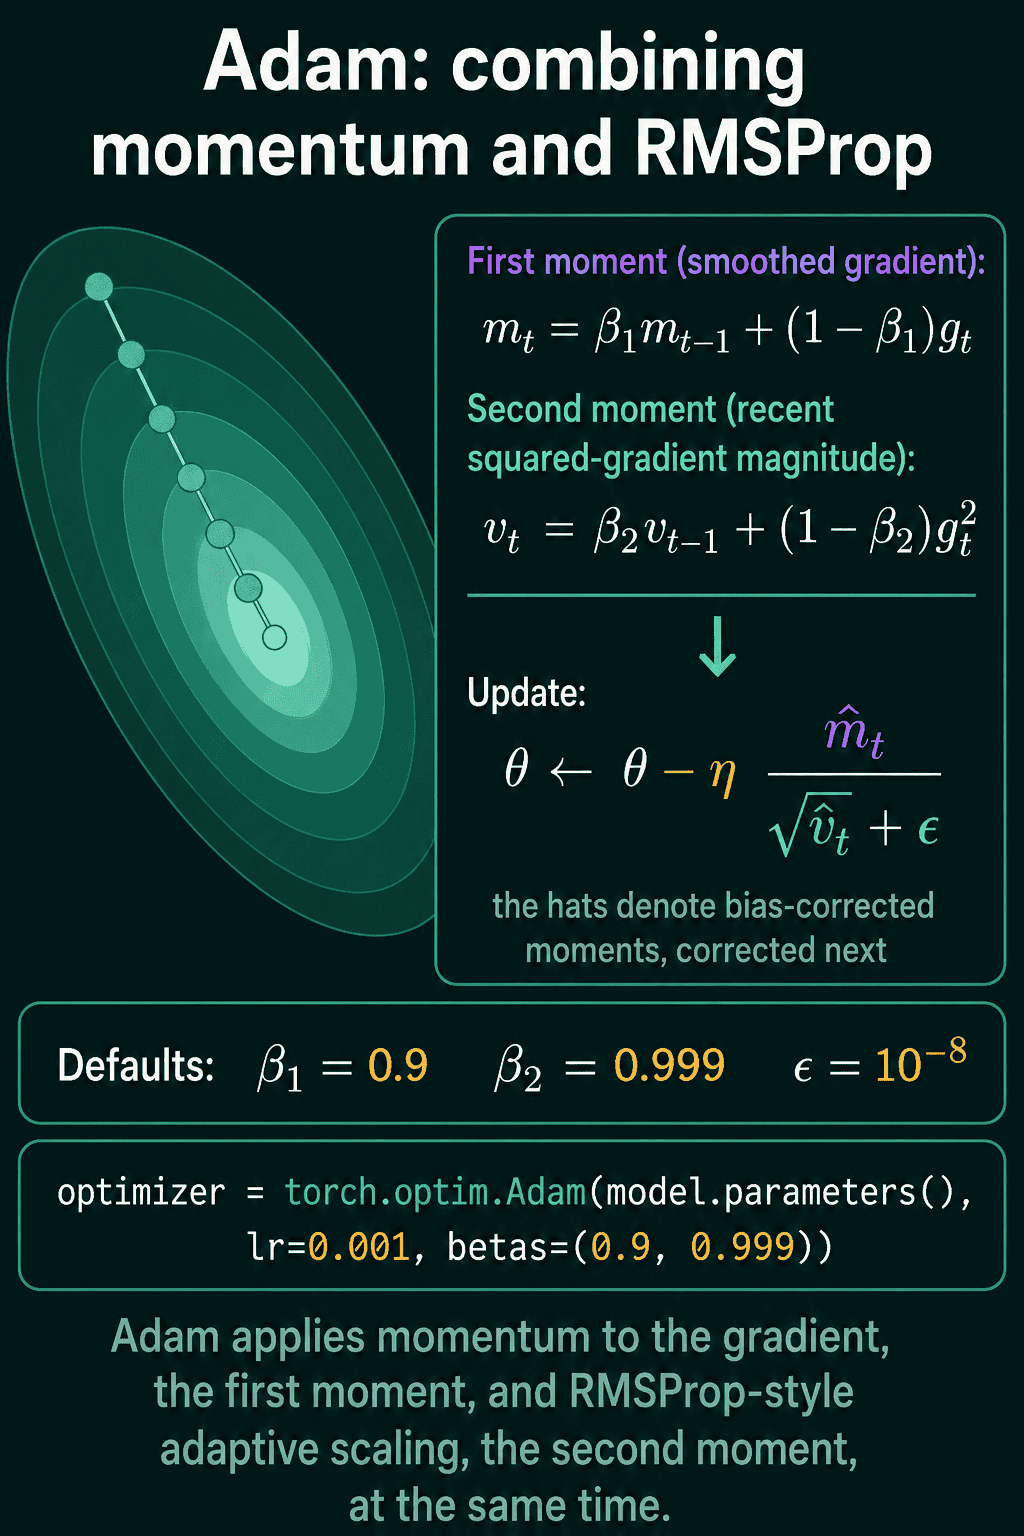
What is the Adam optimizer? Explained step by step
Adam is the optimizer most deep learning models train with. This post explains what it does, why it works better than plain gradient descent, and when to use AdamW instead.
 Optimization
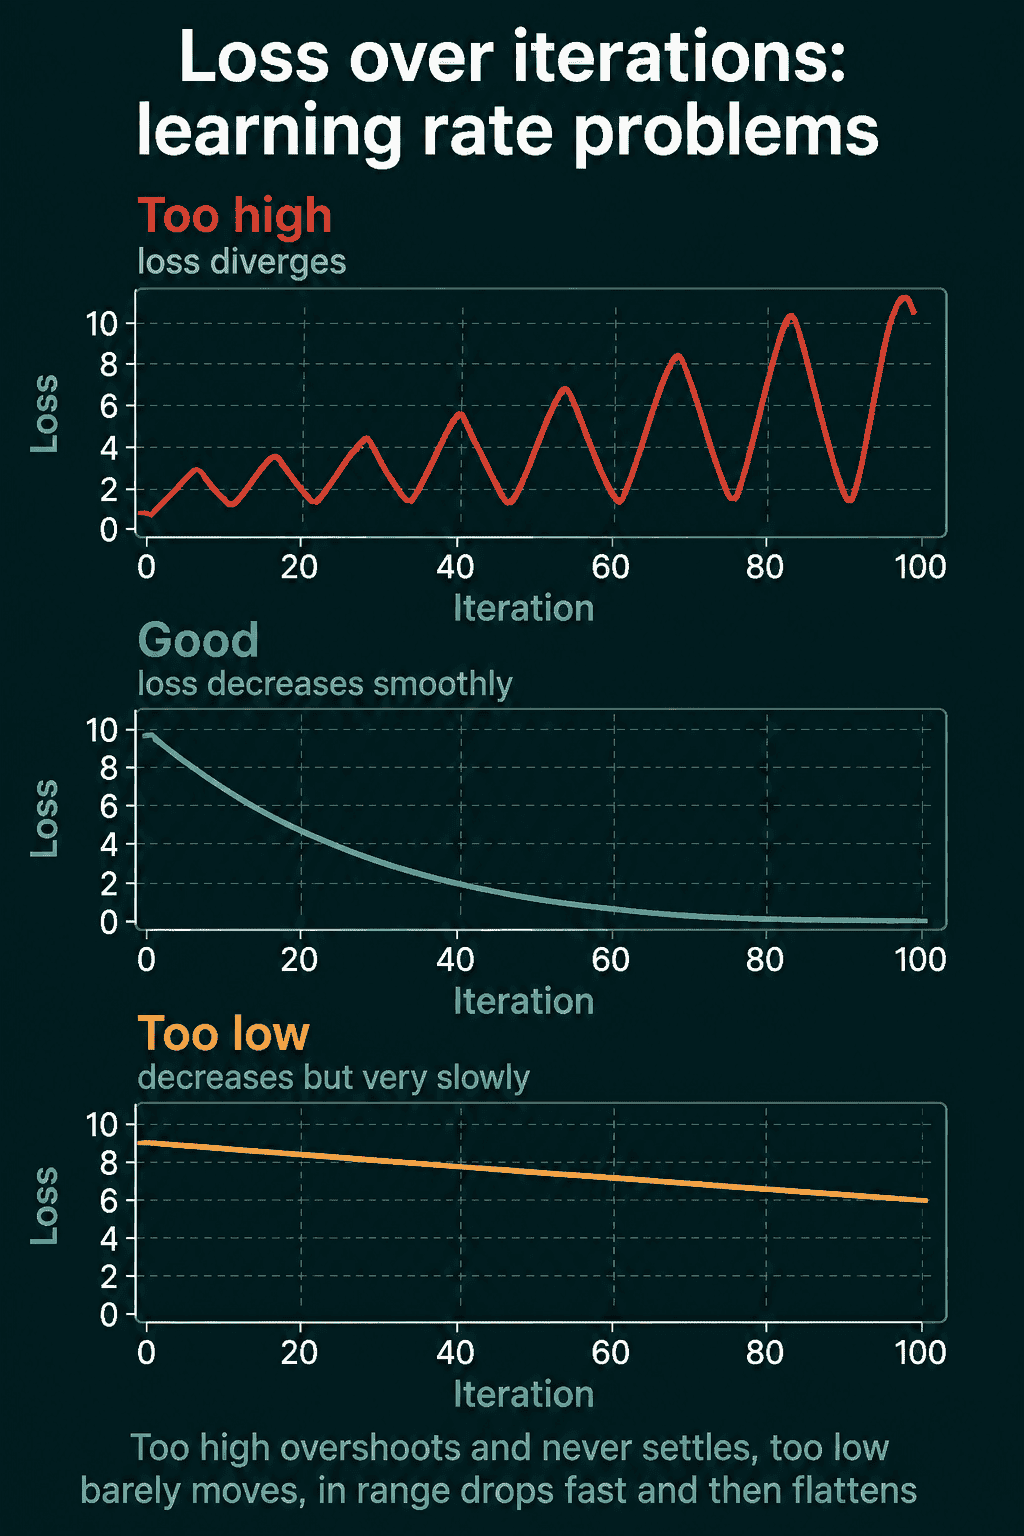
What is a learning rate, and how do you pick one?
The learning rate is the number that most often decides whether a model trains well. This post explains what it does inside the update rule, how to read the three shapes of a loss curve, why good values differ between SGD and Adam, and a five-line test that finds a usable value.
Generalization and regularization
 Generalization and regularization
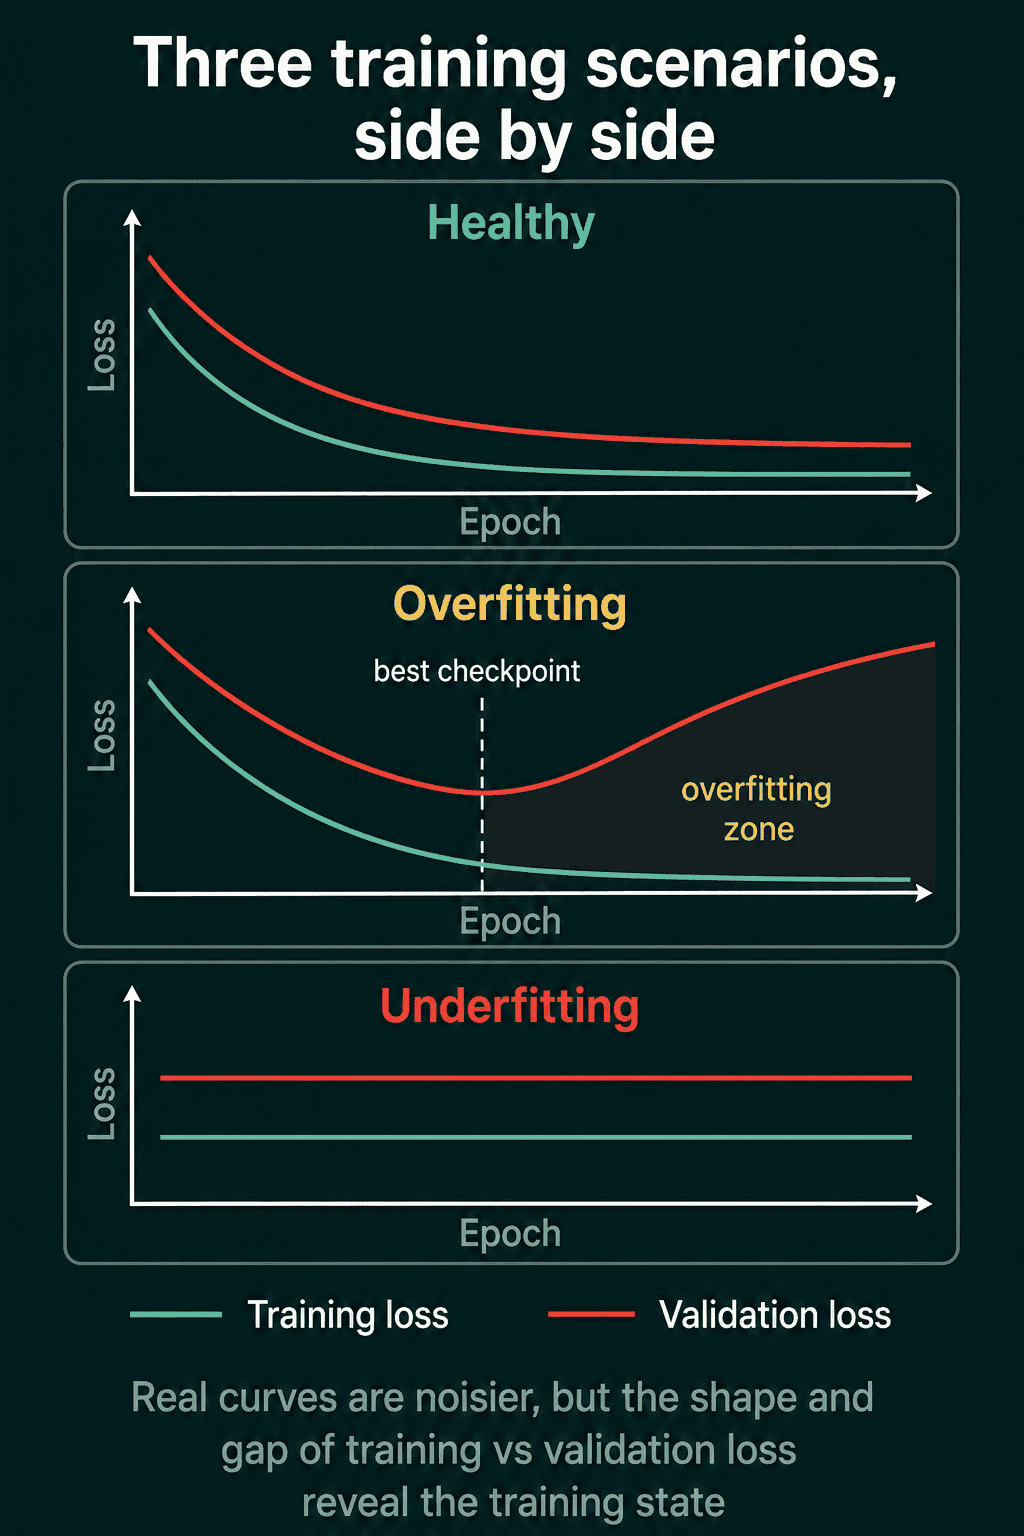
Overfitting vs underfitting: how to tell which one you have, and how to fix it
Overfitting is when a model memorizes its training data and fails on new data. Underfitting is when it cannot even fit the training data. This post shows how to read which one you have from the loss curves and what to change for each.
 Generalization and regularization
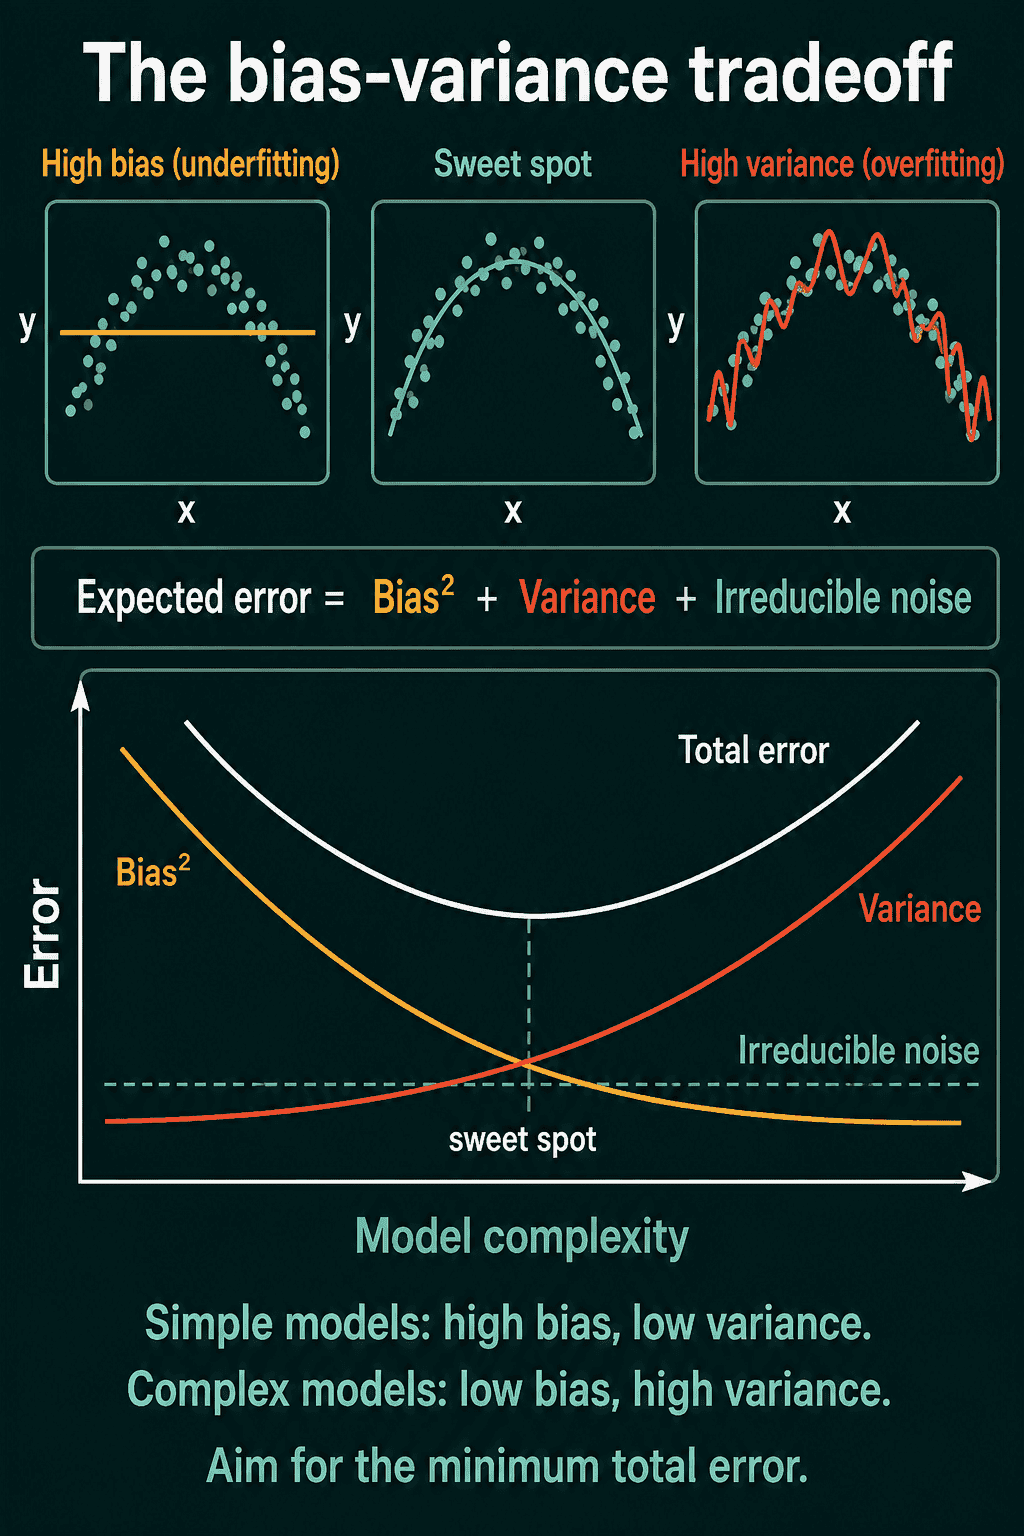
Bias-variance tradeoff explained with pictures
A model can be wrong on new data in two different ways, and the fixes for each pull in opposite directions. This post shows both with plots, how to tell them apart from your training and validation loss, and what to change for each.
 Generalization and regularization
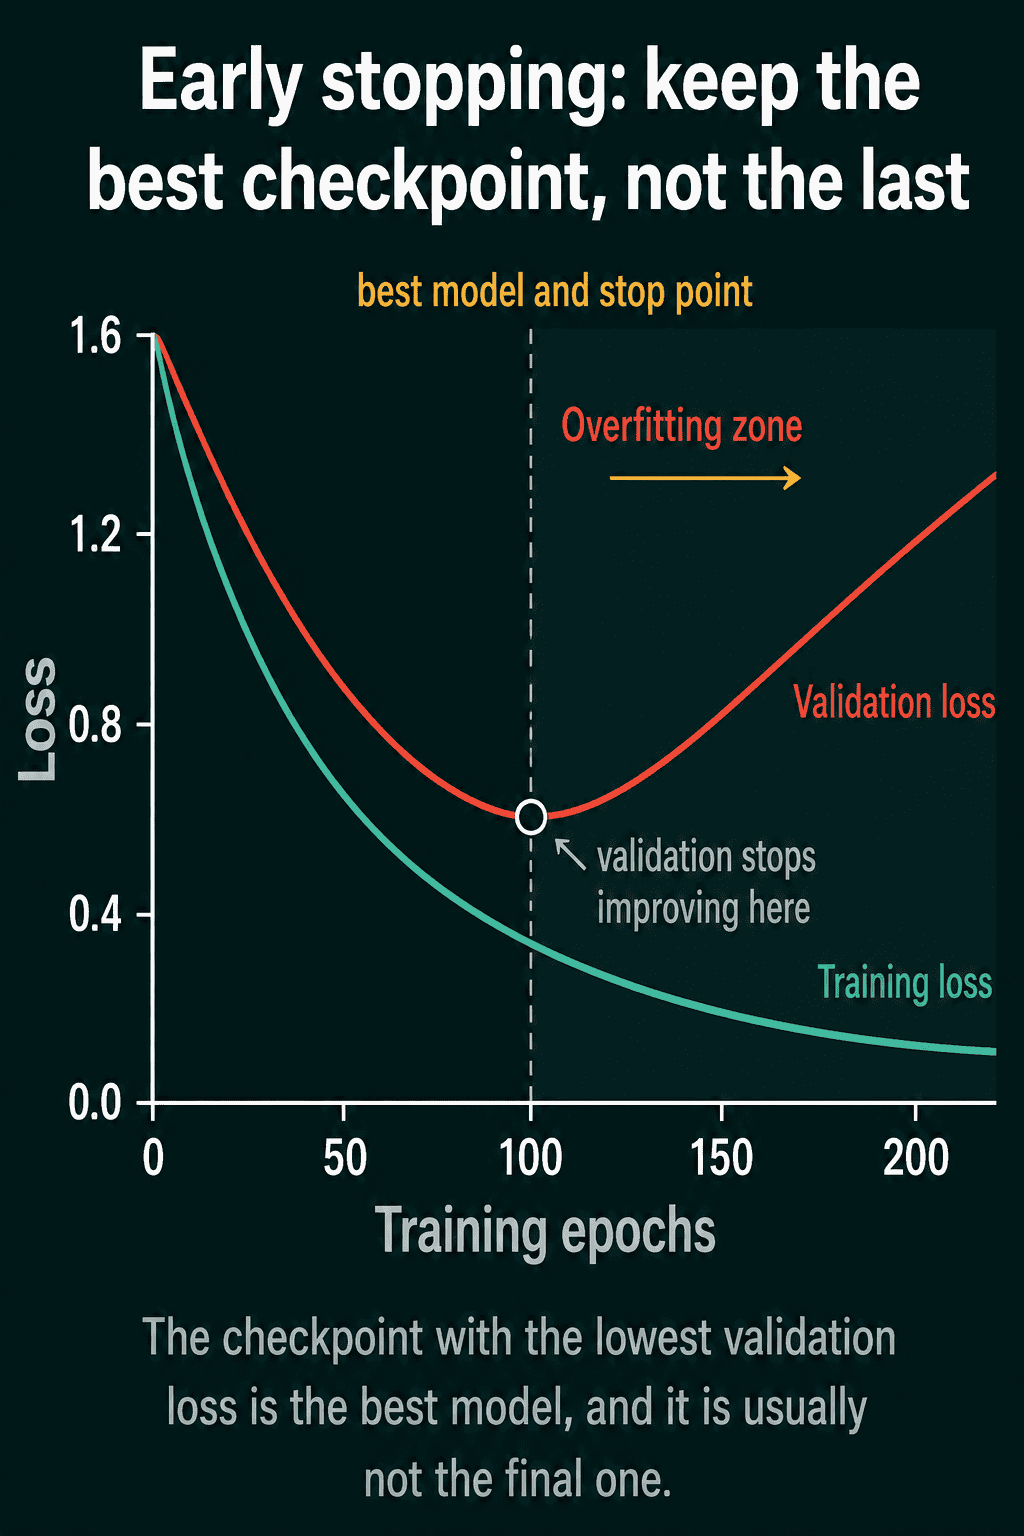
Regularization explained: L1, L2, dropout, and early stopping
Regularization is a set of techniques that stop a model from memorizing its training data so it does better on new data. This post explains four common ones (L2 weight decay, L1, dropout, and early stopping), how each one works, and how to set them in PyTorch.
 Evaluation
My loss is not decreasing: a checklist